Rank #2 of 6 in AI Memory Layers
Install
 vs Mem0
 vs Zep
 vs Supermemory
 vs Cognee
 vs Airweave
Showcase
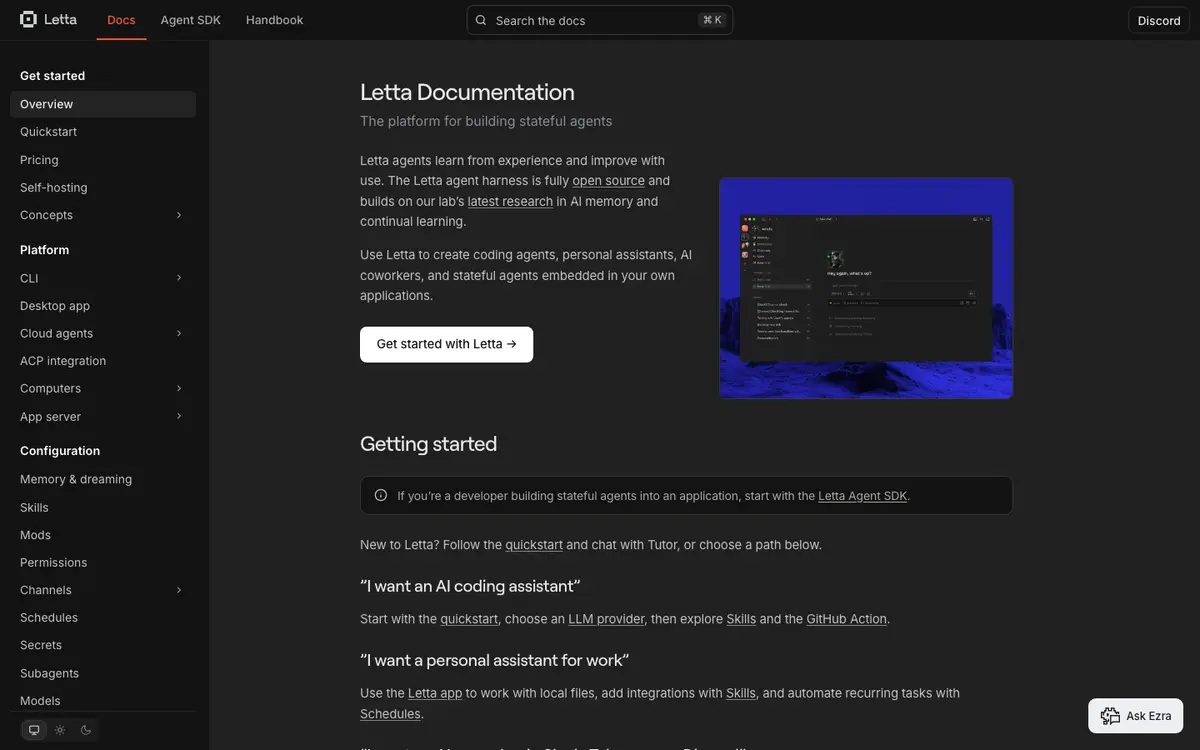
Try itExperimental
See what an agent can do with Letta before you ever sign up. Pick a story: recorded sessions replay real probe-harness transcripts; sandboxed self-drive sessions are designed and gated (docs/TRY-IT.md).
$npx -y @letta-ai/letta-code --versionrecorded session — replayed, not liveVerified integrations
Connections to other tracked products — hover a chip for the verbatim evidence quote behind it.

By theme — the product's score on each story themeBy theme
Agenticness — how well agents can access and operate the productAgenticnessevidence →
How well agents can access and operate the product
Automation depth — how much of the product can run unattendedAutomation depthevidence →
How much of the product can run unattended
Data lifecycle — stories about data lifecycle in this arenaData lifecycleevidence →
Stories about data lifecycle in this arena
Deployment self host — stories about deployment self host in this arenaDeployment self hostevidence →
Stories about deployment self host in this arena
Graph entity memory — stories about graph entity memory in this arenaGraph entity memoryevidence →
Stories about graph entity memory in this arena
Memory recall quality — stories about memory recall quality in this arenaMemory recall qualityevidence →
Stories about memory recall quality in this arena
Openness — open source, data portability, and self-hosting storiesOpennessevidence →
Open source, data portability, and self-hosting stories
Pricing plans — plan structure and value — what each tier costs and what it unlocksPricing plansevidence →
Plan structure and value — what each tier costs and what it unlocks
Privacy posture — data-handling and privacy storiesPrivacy postureevidence →
Data-handling and privacy stories
Retrieval performance — stories about retrieval performance in this arenaRetrieval performanceevidence →
Stories about retrieval performance in this arena
Sdk integrations — stories about sdk integrations in this arenaSdk integrationsevidence →
Stories about sdk integrations in this arena
Session context — stories about session context in this arenaSession contextevidence →
Stories about session context in this arena
Tenancy permissions — stories about tenancy permissions in this arenaTenancy permissionsevidence →
Stories about tenancy permissions in this arena
Story verdicts — every judged story with its evidenceStory verdicts
What’s free: 8 free · 0 paid · 0 enterprise · 27 not stated in evidence
Follow the green: where the map greys out is where Letta stops today. ✓ full · ~ partial · ! disputed · — none · n/a not applicable.
Agenticness — how well agents can access and operate the productAgenticness
How well agents can access and operate the product
API surface
Drive the product through a documented public API
✓8/10
unlocks → Webhooks · Machine-readable spec · Versioning policy · Connect off-the-shelf assistants (Claude, ChatGPT, Cursor) to the same memory so every tool I use shares what it knows about me · Drop the memory layer into agent frameworks like LangChain, LangGraph, CrewAI, or the Vercel AI SDK via documented first-party integrations · Wire memory into real-time voice pipelines (e.g. LiveKit, Pipecat, ElevenLabs) with documented integrations fast enough for live conversation
Subscribe to events via webhooks
—–
Build against official SDKs
✓8/10
Issue scoped/least-privilege API credentials for an agent
~4/10
Connect an agent via an official MCP server
n/an/a
Download a machine-readable API spec (OpenAPI or equivalent)
—0/10
Rely on versioned APIs with a documented deprecation policy
—0/10
Test against a sandbox environment without touching production data
~4/10
Explore an interactive API reference with runnable examples
—0/10
Docs for agents
Point an agent at llms.txt or agent-oriented docs
✓8/10
Agentic features
Delegate tasks to a built-in AI assistant inside the product
✓8/10
Operate the product with natural-language commands
✓8/10
Plug MCP servers into this product so it can use their tools
✓8/10
Get AI-generated insights and suggestions from my data inside the product
~6/10
Set up automations that run autonomously in the background
✓8/10
Automation depth — how much of the product can run unattendedAutomation depth
How much of the product can run unattended
Data lifecycle — stories about data lifecycle in this arenaData lifecycle
Stories about data lifecycle in this arena
Deployment self host — stories about deployment self host in this arenaDeployment self host
Stories about deployment self host in this arena
Graph entity memory — stories about graph entity memory in this arenaGraph entity memory
Stories about graph entity memory in this arena
Memory recall quality — stories about memory recall quality in this arenaMemory recall quality
Stories about memory recall quality in this arena
Openness — open source, data portability, and self-hosting storiesOpenness
Open source, data portability, and self-hosting stories
Pricing plans — plan structure and value — what each tier costs and what it unlocksPricing plans
Plan structure and value — what each tier costs and what it unlocks
Privacy posture — data-handling and privacy storiesPrivacy posture
Data-handling and privacy stories
Retrieval performance — stories about retrieval performance in this arenaRetrieval performance
Stories about retrieval performance in this arena
Sdk integrations — stories about sdk integrations in this arenaSdk integrations
Stories about sdk integrations in this arena
Session context — stories about session context in this arenaSession context
Stories about session context in this arena
Context assembly
Tenancy permissions — stories about tenancy permissions in this arenaTenancy permissions
Stories about tenancy permissions in this arena
Govern who and what can read or write memory with roles, policies, or access-control lists, and audit that access
~3/10
Scope memories per user, agent, or application so one tenant's memories never leak into another's retrieval
~5/10
Share selected memory across multiple agents or users (team or group memory) while keeping private memory private
✓7/10
Sorted by importance (agentic first) (high → low) · 57/57 stories · click a row’s chevron for the rationale and evidence
Delegate tasks to a built-in AI assistant inside the product G Agentic features | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 3 | full | 8/10 | Xcommunity | |
Drive the product through a documented public API G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 3 | full | 8/10 | Tprobed | |
Plug MCP servers into this product so it can use their tools G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 3 | full | 8/10 | Xcommunity | |
Connect an agent via an official MCP server G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 3 | n/a | 0/10 | ||
Build against official SDKs G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | full | 8/10 | Cclaimed | |
Operate the product with natural-language commands G Agentic features | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | full | 8/10 | Xcommunity | |
Point an agent at llms.txt or agent-oriented docs G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | full | 8/10 | Tprobed | |
Run the product headlessly / in CI for automation G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | full | 8/10 | Cclaimed | |
Set up automations that run autonomously in the background G Agentic features | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | full | 8/10 | Xcommunity | |
Use an official CLI G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | full | 8/10 | Tprobed | |
Get AI-generated insights and suggestions from my data inside the product G Agentic features | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | partial | 6/10 | Xcommunity | |
Issue scoped/least-privilege API credentials for an agent G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | partial | 4/10 | Cclaimed | |
Download a machine-readable API spec (OpenAPI or equivalent) G Api quality | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | none | 0/10 | ||
Explore an interactive API reference with runnable examples G Api quality | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | none | 0/10 | ||
Rely on versioned APIs with a documented deprecation policy G Api quality | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | none | 0/10 | ||
Subscribe to events via webhooks G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | none | untested | none yet | |
Test against a sandbox environment without touching production data G Api quality | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 1 | partial | 4/10 | Cclaimed | |
Get summaries of past sessions or threads so an agent can pick up where the last conversation left off C Context assembly | developer | Session context — stories about session context in this arenaSession context | 3 | full | 8/10 | Xcommunity | |
My agent can manage its own memory mid-conversation — adding, searching, updating, and deleting memories through tools or API calls it invokes itself C Agent memory | ai-native user | Memory recall quality — stories about memory recall quality in this arenaMemory recall quality | 3 | full | 8/10 | Xcommunity | |
Self-host the core product G | ai-native user | Openness — open source, data portability, and self-hosting storiesOpenness | 3 | fullfree | 8/10 | Cclaimed | |
Add memories from conversations and retrieve them later with semantic search, so context persists across sessions C Core memory | developer | Memory recall quality — stories about memory recall quality in this arenaMemory recall quality | 3 | partial | 6/10 | Xcommunity | |
Define rules that trigger actions automatically on events G | ai-native user | Automation depth — how much of the product can run unattendedAutomation depth | 3 | partial | 6/10 | Cclaimed | |
Self-host the memory layer from open-source code (e.g. via Docker) on infrastructure I control C Self host | platform-engineer | Deployment self host — stories about deployment self host in this arenaDeployment self host | 3 | partialfree | 6/10 | Tprobed | |
Export all of my data in open formats and leave G | ai-native user | Openness — open source, data portability, and self-hosting storiesOpenness | 3 | partialfree | 5/10 | Xcommunity | |
Scope memories per user, agent, or application so one tenant's memories never leak into another's retrieval C Isolation | developer | Tenancy permissions — stories about tenancy permissions in this arenaTenancy permissions | 3 | partial | 5/10 | Cclaimed | |
Store memories as a knowledge graph of entities and relationships so multi-hop and entity-centric questions are answerable C Knowledge graph | ml-engineer | Graph entity memory — stories about graph entity memory in this arenaGraph entity memory | 3 | none | 0/10 | ||
Prevent my data from being used to train AI models G | ai-native user | Privacy posture — data-handling and privacy storiesPrivacy posture | 3 | nonefree | untested | none yet | |
The memory layer decides for itself what is worth remembering — extracting salient facts from raw conversation and consolidating them in the background C Agent memory | ai-native user | Memory recall quality — stories about memory recall quality in this arenaMemory recall quality | 2 | full | 8/10 | Xcommunity | |
Read the product's source under an open license G | ai-native user | Openness — open source, data portability, and self-hosting storiesOpenness | 2 | partialfree | 6/10 | Tprobed | |
Rely on the memory layer to update, supersede, or merge memories when new information contradicts what was stored C Core memory | developer | Memory recall quality — stories about memory recall quality in this arenaMemory recall quality | 2 | partial | 6/10 | Xcommunity | |
Build against official SDKs in at least Python and TypeScript with equivalent memory APIs C Sdks | developer | Sdk integrations — stories about sdk integrations in this arenaSdk integrations | 2 | partial | 5/10 | Cclaimed | |
Control data retention and deletion G | ai-native user | Privacy posture — data-handling and privacy storiesPrivacy posture | 2 | partialfree | 5/10 | Cclaimed | |
Do everything through the API that I can do in the UI G | ai-native user | Openness — open source, data portability, and self-hosting storiesOpenness | 2 | partial | 5/10 | Tprobed | |
Export memories in a machine-readable format so the memory store is portable and not a lock-in trap C Portability | platform-engineer | Data lifecycle — stories about data lifecycle in this arenaData lifecycle | 2 | partialfree | 5/10 | Cclaimed | |
Ingest documents, JSON, and business data into memory — not just chat transcripts C Ingestion | developer | Session context — stories about session context in this arenaSession context | 2 | partial | 5/10 | Cclaimed | |
See published pricing with a free tier and per-unit rates so I can project memory costs before committing G Pricing | platform-engineer | Pricing plans — plan structure and value — what each tier costs and what it unlocksPricing plans | 2 | partial | 5/10 | Cclaimed | |
Choose where my data is stored (region/residency) G | ai-native user | Privacy posture — data-handling and privacy storiesPrivacy posture | 2 | partialfree | 4/10 | Cclaimed | |
Perform bulk operations across many items at once G | ai-native user | Automation depth — how much of the product can run unattendedAutomation depth | 2 | partial | 4/10 | Cclaimed | |
Steer retrieval with metadata filters, keyword/hybrid search modes, or reranking instead of accepting a single fixed similarity search C Retrieval controls | developer | Memory recall quality — stories about memory recall quality in this arenaMemory recall quality | 2 | partial | 4/10 | Cclaimed | |
Govern who and what can read or write memory with roles, policies, or access-control lists, and audit that access C Governance | platform-engineer | Tenancy permissions — stories about tenancy permissions in this arenaTenancy permissions | 2 | partial | 3/10 | Cclaimed | |
Connect off-the-shelf assistants (Claude, ChatGPT, Cursor) to the same memory so every tool I use shares what it knows about me C Agent memory | ai-native user | Sdk integrations — stories about sdk integrations in this arenaSdk integrations | 2 | none | 0/10 | ||
Delete a user's memories on demand — single memory, per-entity, or full erasure — to satisfy privacy requirements C Forgetting | platform-engineer | Data lifecycle — stories about data lifecycle in this arenaData lifecycle | 2 | none | 0/10 | ||
Make memories expire or decay — via TTL, expiration dates, or recency weighting — so stale facts stop surfacing C Forgetting | developer | Data lifecycle — stories about data lifecycle in this arenaData lifecycle | 2 | none | 0/10 | ||
Retrieve a token-budgeted, prompt-ready context block assembled from relevant memories in one call C Context assembly | developer | Session context — stories about session context in this arenaSession context | 2 | none | 0/10 | ||
See published memory-quality benchmark results (e.g. LongMemEval, LoCoMo) backing the product's recall-accuracy claims C Benchmarks | ml-engineer | Memory recall quality — stories about memory recall quality in this arenaMemory recall quality | 2 | none | 0/10 | ||
Drop the memory layer into agent frameworks like LangChain, LangGraph, CrewAI, or the Vercel AI SDK via documented first-party integrations C Frameworks | developer | Sdk integrations — stories about sdk integrations in this arenaSdk integrations | 2 | none | untested | none yet | |
Ingest at scale with async or batch processing and check the status of background memory operations C Scale | platform-engineer | Retrieval performance — stories about retrieval performance in this arenaRetrieval performance | 2 | none | untested | none yet | |
Opt out of telemetry and usage tracking G | ai-native user | Privacy posture — data-handling and privacy storiesPrivacy posture | 2 | none | untested | none yet | |
Schedule recurring jobs or workflows G | ai-native user | Automation depth — how much of the product can run unattendedAutomation depth | 2 | none | untested | none yet | |
See documented retrieval-latency targets or measured numbers (e.g. p50/p95) backing the product's speed claims C Latency | platform-engineer | Retrieval performance — stories about retrieval performance in this arenaRetrieval performance | 2 | none | untested | none yet | |
Track when facts became valid or invalid (temporal reasoning) so the memory distinguishes current from outdated information C Knowledge graph | ml-engineer | Graph entity memory — stories about graph entity memory in this arenaGraph entity memory | 2 | none | untested | none yet | |
Share selected memory across multiple agents or users (team or group memory) while keeping private memory private C Sharing | developer | Tenancy permissions — stories about tenancy permissions in this arenaTenancy permissions | 1 | full | 7/10 | Cclaimed | |
Run the memory layer fully locally — embedded in-process or against local models — without any cloud dependency C Self host | developer | Deployment self host — stories about deployment self host in this arenaDeployment self host | 1 | partial | 6/10 | Cclaimed | |
Version, review, and roll back my automations G | ai-native user | Automation depth — how much of the product can run unattendedAutomation depth | 1 | partial | 4/10 | Cclaimed | |
Customize the memory schema — entity types, edge types, or ontology — to match my domain C Schema customization | ml-engineer | Graph entity memory — stories about graph entity memory in this arenaGraph entity memory | 1 | none | 0/10 | ||
Store images, PDFs, or other files as memory inputs and recall information from them later C Ingestion | developer | Session context — stories about session context in this arenaSession context | 1 | none | 0/10 | ||
Wire memory into real-time voice pipelines (e.g. LiveKit, Pipecat, ElevenLabs) with documented integrations fast enough for live conversation C Frameworks | developer | Sdk integrations — stories about sdk integrations in this arenaSdk integrations | 1 | none | 0/10 |
Opportunities — the stories that would move this product's scores, from its own judged verdictsOpportunitiestop 8 of 42 stories with headroom
What would move Letta’s scores — derived from its own judged verdicts, biggest headroom first. Each line quotes what the judge found missing; shipping it (or evidencing it publicly) is the fix.
Graph entity memory — stories about graph entity memory in this arenaStore memories as a knowledge graph of entities and relationships so multi-hop and entity-centric questions are answerable
nonemoves PA Scoreimpact 30
Letta's documented memory system is file/text-based (MemFS, memory blocks) with optional keyword/semantic/hybrid search (letta-docs-28, letta-docs-41), not a graph of entities and relationships; a Letta employee explicitly frames its approach as 'primarily text/files based' as an alternative to structured memory graphs (letta-comm-10).
Privacy posture — data-handling and privacy storiesPrevent my data from being used to train AI models
nonemoves PA Scoreimpact 30
No evidence pack item addresses data-training opt-out, a training-data policy, or any privacy controls preventing use of user data for model training; self-hosting is mentioned but not tied to a training-data guarantee.
Agenticness — how well agents can access and operate the productSubscribe to events via webhooks
nonemoves agent-readyimpact 30
The evidence pack covers agent SDK streaming, subagents, mods, scheduled tasks, and Slack/GitHub integrations, but there is no mention of a webhook subscription mechanism for events (e.g., agent state changes, task completion) that external systems could subscribe to.
Agenticness — how well agents can access and operate the productExplore an interactive API reference with runnable examples
nonemoves API qualityimpact 30
The evidence pack shows extensive SDK documentation (agent-sdk pages) but no interactive API reference or runnable-example explorer; a direct probe for OpenAPI/Swagger endpoints returned 404 on all candidate paths, indicating no such interactive reference exists.
Agenticness — how well agents can access and operate the productDownload a machine-readable API spec (OpenAPI or equivalent)
nonemoves API qualityimpact 30
Direct probes for OpenAPI/Swagger specs at all standard paths (docs.letta.com/openapi.json, swagger.json, api/openapi.json, .well-known/openapi.json) returned 404, and no documentation elsewhere in the evidence pack references a downloadable machine-readable API spec.
Agenticness — how well agents can access and operate the productRely on versioned APIs with a documented deprecation policy
nonemoves API qualityimpact 30
No evidence anywhere in the pack of API versioning schemes or a documented deprecation policy; the openapi.json probe even 404s, indicating no discoverable API spec that would carry version/deprecation info.
Sdk integrations — stories about sdk integrations in this arenaConnect off-the-shelf assistants (Claude, ChatGPT, Cursor) to the same memory so every tool I use shares what it knows about me
nonemoves PA Scoreimpact 20
Evidence shows Letta integrating with Codex, Claude Code, Hermes Agent, OpenClaw for skills (docs-57), and offering an OpenAI-compatible API for tools like Open WebUI plus an ACP adapter for Zed (docs-23), but nothing shows Letta connecting to or sharing memory with off-the-shelf Claude, ChatGPT, or Cursor specifically.
Retrieval performance — stories about retrieval performance in this arenaIngest at scale with async or batch processing and check the status of background memory operations
nonemoves PA Scoreimpact 20
Letta's docs describe per-agent memory consolidation ('dreaming' background subagents, triggers on steps/compaction) but there is no evidence of a bulk/batch ingestion pipeline for scale data loading nor any API/CLI to check the status of background memory jobs, which is what this platform-engineer story requires.
Showing the top 8 of 42 — every none/partial verdict in the story verdicts table is headroom.
Think a verdict is wrong? Every verdicts-table row has a Flag link — see the methodology.
Coverage map — which docs area, API section, or community source covers which judged storiesCoverage map11 surfaces · 36 covered stories
Where the cited evidence behind each covered verdict came from — the same citations the verdicts table shows, no extra judging.
Platform docs18 stories
- Run the product headlessly / in CI for automation
- Use an official CLI
- Drive the product through a documented public API
- Issue scoped/least-privilege API credentials for an agent
- Set up automations that run autonomously in the background
- Delegate tasks to a built-in AI assistant inside the product
- Operate the product with natural-language commands
- Test against a sandbox environment without touching production data
- Perform bulk operations across many items at once
- Define rules that trigger actions automatically on events
- Export memories in a machine-readable format so the memory store is portable and not a lock-in trap
- Run the memory layer fully locally — embedded in-process or against local models — without any cloud dependency
- Self-host the memory layer from open-source code (e.g. via Docker) on infrastructure I control
- Do everything through the API that I can do in the UI
- Self-host the core product
- Choose where my data is stored (region/residency)
- Control data retention and deletion
- Get summaries of past sessions or threads so an agent can pick up where the last conversation left off
Agent SDK docs17 stories
- Point an agent at llms.txt or agent-oriented docs
- Run the product headlessly / in CI for automation
- Plug MCP servers into this product so it can use their tools
- Drive the product through a documented public API
- Issue scoped/least-privilege API credentials for an agent
- Build against official SDKs
- Get AI-generated insights and suggestions from my data inside the product
- Set up automations that run autonomously in the background
- Define rules that trigger actions automatically on events
- Export memories in a machine-readable format so the memory store is portable and not a lock-in trap
- The memory layer decides for itself what is worth remembering — extracting salient facts from raw conversation and consolidating them in the background
- Do everything through the API that I can do in the UI
- Export all of my data in open formats and leave
- Build against official SDKs in at least Python and TypeScript with equivalent memory APIs
- Get summaries of past sessions or threads so an agent can pick up where the last conversation left off
- Ingest documents, JSON, and business data into memory — not just chat transcripts
- Scope memories per user, agent, or application so one tenant's memories never leak into another's retrieval
Configuration docs16 stories
- Issue scoped/least-privilege API credentials for an agent
- Get AI-generated insights and suggestions from my data inside the product
- Set up automations that run autonomously in the background
- Delegate tasks to a built-in AI assistant inside the product
- Operate the product with natural-language commands
- Perform bulk operations across many items at once
- Define rules that trigger actions automatically on events
- Version, review, and roll back my automations
- Run the memory layer fully locally — embedded in-process or against local models — without any cloud dependency
- My agent can manage its own memory mid-conversation — adding, searching, updating, and deleting memories through tools or API calls it invokes itself
- The memory layer decides for itself what is worth remembering — extracting salient facts from raw conversation and consolidating them in the background
- Add memories from conversations and retrieve them later with semantic search, so context persists across sessions
- Rely on the memory layer to update, supersede, or merge memories when new information contradicts what was stored
- Do everything through the API that I can do in the UI
- Get summaries of past sessions or threads so an agent can pick up where the last conversation left off
- Ingest documents, JSON, and business data into memory — not just chat transcripts
Concepts docs14 stories
- Get AI-generated insights and suggestions from my data inside the product
- Operate the product with natural-language commands
- Version, review, and roll back my automations
- Export memories in a machine-readable format so the memory store is portable and not a lock-in trap
- Run the memory layer fully locally — embedded in-process or against local models — without any cloud dependency
- My agent can manage its own memory mid-conversation — adding, searching, updating, and deleting memories through tools or API calls it invokes itself
- Add memories from conversations and retrieve them later with semantic search, so context persists across sessions
- Steer retrieval with metadata filters, keyword/hybrid search modes, or reranking instead of accepting a single fixed similarity search
- Do everything through the API that I can do in the UI
- Export all of my data in open formats and leave
- Get summaries of past sessions or threads so an agent can pick up where the last conversation left off
- Ingest documents, JSON, and business data into memory — not just chat transcripts
- Scope memories per user, agent, or application so one tenant's memories never leak into another's retrieval
- Share selected memory across multiple agents or users (team or group memory) while keeping private memory private
Hacker News12 stories
- Plug MCP servers into this product so it can use their tools
- Use an official CLI
- Get AI-generated insights and suggestions from my data inside the product
- Set up automations that run autonomously in the background
- Delegate tasks to a built-in AI assistant inside the product
- Operate the product with natural-language commands
- My agent can manage its own memory mid-conversation — adding, searching, updating, and deleting memories through tools or API calls it invokes itself
- The memory layer decides for itself what is worth remembering — extracting salient facts from raw conversation and consolidating them in the background
- Add memories from conversations and retrieve them later with semantic search, so context persists across sessions
- Rely on the memory layer to update, supersede, or merge memories when new information contradicts what was stored
- Export all of my data in open formats and leave
- Get summaries of past sessions or threads so an agent can pick up where the last conversation left off
Self hosting docs9 stories
- Export memories in a machine-readable format so the memory store is portable and not a lock-in trap
- Run the memory layer fully locally — embedded in-process or against local models — without any cloud dependency
- Self-host the memory layer from open-source code (e.g. via Docker) on infrastructure I control
- Do everything through the API that I can do in the UI
- Export all of my data in open formats and leave
- Read the product's source under an open license
- Self-host the core product
- Choose where my data is stored (region/residency)
- Control data retention and deletion
Pricing docs6 stories
- Issue scoped/least-privilege API credentials for an agent
- Perform bulk operations across many items at once
- See published pricing with a free tier and per-unit rates so I can project memory costs before committing
- Govern who and what can read or write memory with roles, policies, or access-control lists, and audit that access
- Scope memories per user, agent, or application so one tenant's memories never leak into another's retrieval
- Share selected memory across multiple agents or users (team or group memory) while keeping private memory private
GitHub README4 stories
llms.txt3 stories
OpenAPI spec2 stories
Probe proofs — replayable recordings from the probe harnessProbe proofs
Replayable recordings from our probe harness — see the Prove-It protocol to submit one.
$npx -y @letta-ai/letta-code --versionreproduced$ npx -y @letta-ai/letta-code --version \|/-0.31.12 (Letta Code) \
$npx -y @letta-ai/letta-code server --backend local --listen ws://127.0.0.1:4500 # keyless boot, then killreproduced$ npx -y @letta-ai/letta-code server --backend local --listen ws://127.0.0.1:4500 # [redacted]less boot, then kill Listening on ws://127.0.0.1:4500 WebSocket: ws://127.0.0.1:4500/ws
Claims vs evidence — vendor claims reconciled against independent verdictsClaims vs evidence
4 of 13 testable claims verified · 0 contradicted → integrity 31/100
24 distinct capability claims found in Letta’s own claimed-docs/GitHub materials, reconciled against our judge’s independent verdicts.
4
Verified
9
Unverified
0
Contradicted
23
Undersold
Verified (5)
“Agents can be created once and resumed later from any device or session, preserving context”
Add memories from conversations and retrieve them later with semantic search, so context persists across sessionspartialproof ↗
“Self-hosted App Server deploys the Letta agent harness as an always-on service you control”
Self-host the memory layer from open-source code (e.g. via Docker) on infrastructure I controlpartialproof ↗
“Dreaming (background memory consolidation) can be triggered after N steps, on context compaction, or never”
The memory layer decides for itself what is worth remembering — extracting salient facts from raw conversation and consolidating them in the backgroundfullproof ↗
“Background subagents review recent conversations, consolidate lessons, and update memory without interrupting active work”
The memory layer decides for itself what is worth remembering — extracting salient facts from raw conversation and consolidating them in the backgroundfullproof ↗
“App Server exposes an OpenAI-compatible API (and an ACP adapter) usable by clients like Open WebUI or Zed”
Drive the product through a documented public APIfullproof ↗
Unverified (10)
“Headless mode runs the CLI non-interactively for scripting, CI/CD pipelines, or UNIX-style composition”
Run the product headlessly / in CI for automationfullproof ↗
“Shared memory repositories (Git-backed, hosted in Letta Cloud) give multiple agents access to the same files and working context”
Share selected memory across multiple agents or users (team or group memory) while keeping private memory privatefullproof ↗
“CLI command to create a named shared-memory workspace for a team”
Share selected memory across multiple agents or users (team or group memory) while keeping private memory privatefullproof ↗
“Custom starting memory can be passed in, with each entry stored as a Markdown file in the agent's memory repository”
Export memories in a machine-readable format so the memory store is portable and not a lock-in trappartialproof ↗
“Web app runs agents in a managed cloud sandbox by default, requiring no local environment setup”
Test against a sandbox environment without touching production datapartialproof ↗
“Installing the MemFS Search mod adds keyword, semantic, or hybrid search over memory”
Steer retrieval with metadata filters, keyword/hybrid search modes, or reranking instead of accepting a single fixed similarity searchpartialproof ↗
“Agents can run entirely on infrastructure you control, with no dependency on Letta Cloud”
“Default local mode stores agent state on your own machine and requires no Letta account/login”
Run the memory layer fully locally — embedded in-process or against local models — without any cloud dependencypartialproof ↗
“Plan supports up to 20 stateful agents”
See published pricing with a free tier and per-unit rates so I can project memory costs before committingpartialproof ↗
“Official Letta Agent SDK for building agents into TypeScript applications”
Undersold (23)
Point an agent at llms.txt or agent-oriented docsfullproof ↗
Plug MCP servers into this product so it can use their toolsfullproof ↗
Issue scoped/least-privilege API credentials for an agentpartialproof ↗
Get AI-generated insights and suggestions from my data inside the productpartialproof ↗
Set up automations that run autonomously in the backgroundfullproof ↗
Delegate tasks to a built-in AI assistant inside the productfullproof ↗
Operate the product with natural-language commandsfullproof ↗
Perform bulk operations across many items at oncepartialproof ↗
Define rules that trigger actions automatically on eventspartialproof ↗
My agent can manage its own memory mid-conversation — adding, searching, updating, and deleting memories through tools or API calls it invokes itselffullproof ↗
Rely on the memory layer to update, supersede, or merge memories when new information contradicts what was storedpartialproof ↗
Do everything through the API that I can do in the UIpartialproof ↗
Export all of my data in open formats and leavepartialproof ↗
Read the product's source under an open licensepartialproof ↗
Choose where my data is stored (region/residency)partialproof ↗
Build against official SDKs in at least Python and TypeScript with equivalent memory APIspartialproof ↗
Get summaries of past sessions or threads so an agent can pick up where the last conversation left offfullproof ↗
Ingest documents, JSON, and business data into memory — not just chat transcriptspartialproof ↗
Govern who and what can read or write memory with roles, policies, or access-control lists, and audit that accesspartialproof ↗
Scope memories per user, agent, or application so one tenant's memories never leak into another's retrievalpartialproof ↗
Claims outside our story set (9)
Real capability claims found in Letta’s own materials, but no story in this arena’s taxonomy covers them yet — that’s feedback on the taxonomy, not a mark against the product.
“/fork command branches the current conversation, including its in-context history, without altering the original”
source ↗“Users can explicitly teach the agent persistent instructions via a /remember command”
source ↗“Signing in backs up agents to the cloud, making them available via chat.letta.com, desktop app, remote machines, and messaging integrations”
source ↗“/doctor command audits the memory hierarchy for drift, duplication, and system-prompt token usage”
source ↗“--ephemeral flag runs a one-shot task without creating or persisting any agent, memory, or filesystem state”
source ↗“/agents command lets you browse and switch between agents, with pinning/favoriting support”
source ↗“/btw command forks the conversation in the background to answer a side question without interrupting the main task”
source ↗“Connecting your own machine via an environment picker gives the agent access to local files and tools”
source ↗“GitHub organizations can be synced into Letta via an Integrations page”
source ↗
Business model
Apache-2.0 open-source framework and self-hostable App Server; Letta Cloud adds a free tier then usage/credit-based paid plans and custom enterprise contracts.
pricing ↗Score trend
How this product’s scores have moved as evidence and verdicts are re-derived — a point per change, not per day.
Try Experimental
Run it in the microterminal →Recorded agent sessions — and a live MCP handshake where the vendor ships one.
Flag
⚑ Flag a verdictThink a verdict is wrong? Opens a prefilled GitHub issue — or use the ⚑ next to any verdict above.
For agents
Agent surface uptime llms.txt 100% (30d, checked every 6h since Sep 8 '26)