Rank #1 of 6 in AI Memory Layers
 vs Zep
 vs Letta
 vs Supermemory
 vs Cognee
 vs Airweave
Showcase
Try itExperimental
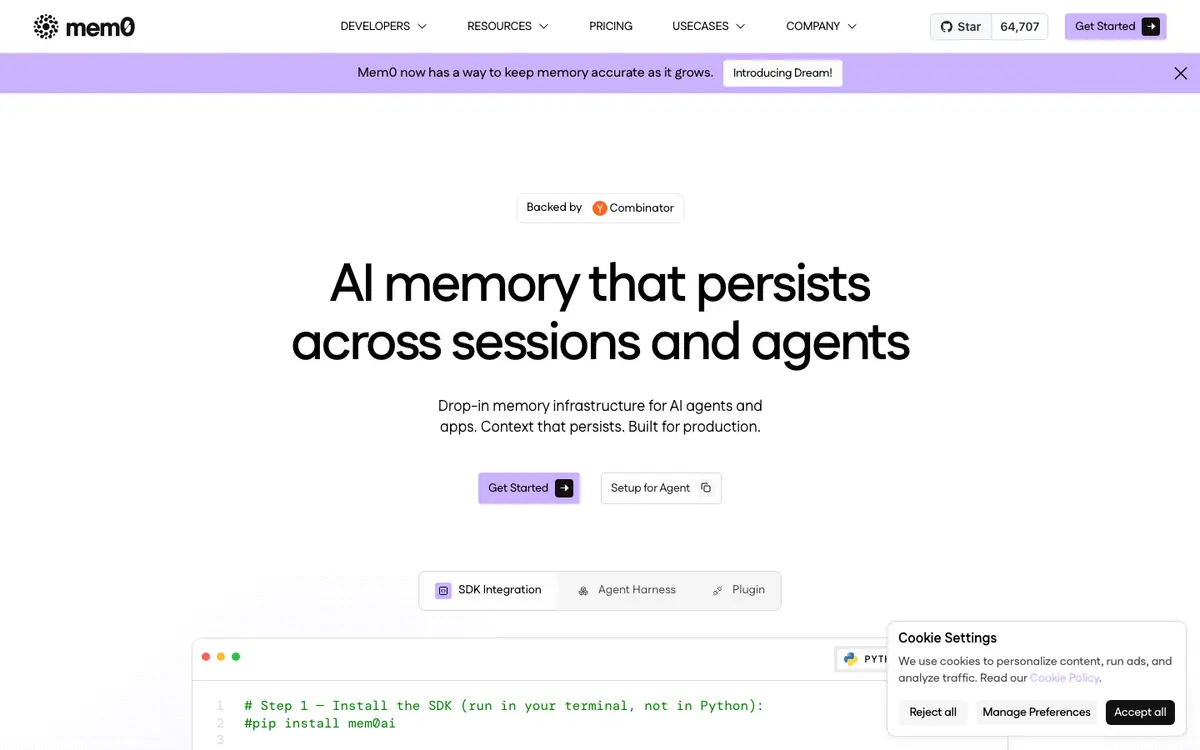
See what an agent can do with Mem0 before you ever sign up. Pick a story: recorded sessions replay real probe-harness transcripts; the live MCP handshake runs real requests from our edge, right now — including, where the server allows it, one real read-only tool call (bring your own key for auth-gated servers); sandboxed self-drive sessions are designed and gated (docs/TRY-IT.md).
$uvx --from mem0-cli mem0 --helprecorded session — replayed, not liveVerified integrations
Connections to other tracked products — hover a chip for the verbatim evidence quote behind it.


By theme — the product's score on each story themeBy theme
Agenticness — how well agents can access and operate the productAgenticnessevidence →
How well agents can access and operate the product
Automation depth — how much of the product can run unattendedAutomation depthevidence →
How much of the product can run unattended
Data lifecycle — stories about data lifecycle in this arenaData lifecycleevidence →
Stories about data lifecycle in this arena
Deployment self host — stories about deployment self host in this arenaDeployment self hostevidence →
Stories about deployment self host in this arena
Graph entity memory — stories about graph entity memory in this arenaGraph entity memoryevidence →
Stories about graph entity memory in this arena
Memory recall quality — stories about memory recall quality in this arenaMemory recall qualityevidence →
Stories about memory recall quality in this arena
Openness — open source, data portability, and self-hosting storiesOpennessevidence →
Open source, data portability, and self-hosting stories
Pricing plans — plan structure and value — what each tier costs and what it unlocksPricing plansevidence →
Plan structure and value — what each tier costs and what it unlocks
Privacy posture — data-handling and privacy storiesPrivacy postureevidence →
Data-handling and privacy stories
Retrieval performance — stories about retrieval performance in this arenaRetrieval performanceevidence →
Stories about retrieval performance in this arena
Sdk integrations — stories about sdk integrations in this arenaSdk integrationsevidence →
Stories about sdk integrations in this arena
Session context — stories about session context in this arenaSession contextevidence →
Stories about session context in this arena
Tenancy permissions — stories about tenancy permissions in this arenaTenancy permissionsevidence →
Stories about tenancy permissions in this arena
Story verdicts — every judged story with its evidenceStory verdicts
What’s free: 2 free · 0 paid · 0 enterprise · 38 not stated in evidence
Follow the green: where the map greys out is where Mem0 stops today. ✓ full · ~ partial · ! disputed · — none · n/a not applicable.
Agenticness — how well agents can access and operate the productAgenticness
How well agents can access and operate the product
API surface
Drive the product through a documented public API
✓9/10
unlocks → Versioning policy · API sandbox · Wire memory into real-time voice pipelines (e.g. LiveKit, Pipecat, ElevenLabs) with documented integrations fast enough for live conversation
Subscribe to events via webhooks
✓8/10
Build against official SDKs
✓8/10
Issue scoped/least-privilege API credentials for an agent
~5/10
Connect an agent via an official MCP server
✓8/10
Download a machine-readable API spec (OpenAPI or equivalent)
✓9/10
Rely on versioned APIs with a documented deprecation policy
—–
Test against a sandbox environment without touching production data
—–
Explore an interactive API reference with runnable examples
~4/10
Docs for agents
Point an agent at llms.txt or agent-oriented docs
✓9/10
Agentic features
Delegate tasks to a built-in AI assistant inside the product
n/an/a
Operate the product with natural-language commands
~6/10
Plug MCP servers into this product so it can use their tools
n/an/a
Get AI-generated insights and suggestions from my data inside the product
~4/10
Set up automations that run autonomously in the background
n/an/a
Automation depth — how much of the product can run unattendedAutomation depth
How much of the product can run unattended
Data lifecycle — stories about data lifecycle in this arenaData lifecycle
Stories about data lifecycle in this arena
Deployment self host — stories about deployment self host in this arenaDeployment self host
Stories about deployment self host in this arena
Graph entity memory — stories about graph entity memory in this arenaGraph entity memory
Stories about graph entity memory in this arena
Memory recall quality — stories about memory recall quality in this arenaMemory recall quality
Stories about memory recall quality in this arena
Openness — open source, data portability, and self-hosting storiesOpenness
Open source, data portability, and self-hosting stories
Pricing plans — plan structure and value — what each tier costs and what it unlocksPricing plans
Plan structure and value — what each tier costs and what it unlocks
Privacy posture — data-handling and privacy storiesPrivacy posture
Data-handling and privacy stories
Retrieval performance — stories about retrieval performance in this arenaRetrieval performance
Stories about retrieval performance in this arena
Sdk integrations — stories about sdk integrations in this arenaSdk integrations
Stories about sdk integrations in this arena
Session context — stories about session context in this arenaSession context
Stories about session context in this arena
Context assembly
Tenancy permissions — stories about tenancy permissions in this arenaTenancy permissions
Stories about tenancy permissions in this arena
Govern who and what can read or write memory with roles, policies, or access-control lists, and audit that access
~4/10
Scope memories per user, agent, or application so one tenant's memories never leak into another's retrieval
✓7/10
Share selected memory across multiple agents or users (team or group memory) while keeping private memory private
~5/10
Sorted by importance (agentic first) (high → low) · 57/57 stories · click a row’s chevron for the rationale and evidence
Drive the product through a documented public API G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 3 | full | 9/10 | Tprobed | |
Connect an agent via an official MCP server G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 3 | full | 8/10 | Tprobed | |
Plug MCP servers into this product so it can use their tools G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 3 | n/a | 0/10 | ||
Delegate tasks to a built-in AI assistant inside the product G Agentic features | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 3 | n/a | untested | none yet | |
Download a machine-readable API spec (OpenAPI or equivalent) G Api quality | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | full | 9/10 | Tprobed | |
Point an agent at llms.txt or agent-oriented docs G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | full | 9/10 | Tprobed | |
Build against official SDKs G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | full | 8/10 | Tprobed | |
Run the product headlessly / in CI for automation G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | full | 8/10 | Tprobed | |
Subscribe to events via webhooks G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | full | 8/10 | Cclaimed | |
Use an official CLI G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | full | 8/10 | Tprobed | |
Operate the product with natural-language commands G Agentic features | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | partial | 6/10 | Cclaimed | |
Issue scoped/least-privilege API credentials for an agent G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | partial | 5/10 | Cclaimed | |
Explore an interactive API reference with runnable examples G Api quality | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | partial | 4/10 | Tprobed | |
Get AI-generated insights and suggestions from my data inside the product G Agentic features | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | partial | 4/10 | Cclaimed | |
Rely on versioned APIs with a documented deprecation policy G Api quality | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | none | untested | none yet | |
Set up automations that run autonomously in the background G Agentic features | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | n/a | untested | none yet | |
Test against a sandbox environment without touching production data G Api quality | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 1 | none | untested | none yet | |
Add memories from conversations and retrieve them later with semantic search, so context persists across sessions C Core memory | developer | Memory recall quality — stories about memory recall quality in this arenaMemory recall quality | 3 | full | 8/10 | Xcommunity | |
My agent can manage its own memory mid-conversation — adding, searching, updating, and deleting memories through tools or API calls it invokes itself C Agent memory | ai-native user | Memory recall quality — stories about memory recall quality in this arenaMemory recall quality | 3 | full | 8/10 | Tprobed | |
Self-host the core product G | ai-native user | Openness — open source, data portability, and self-hosting storiesOpenness | 3 | fullfree | 8/10 | Cclaimed | |
Store memories as a knowledge graph of entities and relationships so multi-hop and entity-centric questions are answerable C Knowledge graph | ml-engineer | Graph entity memory — stories about graph entity memory in this arenaGraph entity memory | 3 | full | 8/10 | Cclaimed | |
Scope memories per user, agent, or application so one tenant's memories never leak into another's retrieval C Isolation | developer | Tenancy permissions — stories about tenancy permissions in this arenaTenancy permissions | 3 | full | 7/10 | Cclaimed | |
Self-host the memory layer from open-source code (e.g. via Docker) on infrastructure I control C Self host | platform-engineer | Deployment self host — stories about deployment self host in this arenaDeployment self host | 3 | fullfree | 7/10 | Cclaimed | |
Export all of my data in open formats and leave G | ai-native user | Openness — open source, data portability, and self-hosting storiesOpenness | 3 | partial | 6/10 | Cclaimed | |
Get summaries of past sessions or threads so an agent can pick up where the last conversation left off C Context assembly | developer | Session context — stories about session context in this arenaSession context | 3 | partial | 6/10 | Tprobed | |
Define rules that trigger actions automatically on events G | ai-native user | Automation depth — how much of the product can run unattendedAutomation depth | 3 | partial | 4/10 | Cclaimed | |
Prevent my data from being used to train AI models G | ai-native user | Privacy posture — data-handling and privacy storiesPrivacy posture | 3 | none | untested | none yet | |
Connect off-the-shelf assistants (Claude, ChatGPT, Cursor) to the same memory so every tool I use shares what it knows about me C Agent memory | ai-native user | Sdk integrations — stories about sdk integrations in this arenaSdk integrations | 2 | full | 8/10 | Tprobed | |
Export memories in a machine-readable format so the memory store is portable and not a lock-in trap C Portability | platform-engineer | Data lifecycle — stories about data lifecycle in this arenaData lifecycle | 2 | full | 7/10 | Cclaimed | |
Make memories expire or decay — via TTL, expiration dates, or recency weighting — so stale facts stop surfacing C Forgetting | developer | Data lifecycle — stories about data lifecycle in this arenaData lifecycle | 2 | full | 7/10 | Cclaimed | |
The memory layer decides for itself what is worth remembering — extracting salient facts from raw conversation and consolidating them in the background C Agent memory | ai-native user | Memory recall quality — stories about memory recall quality in this arenaMemory recall quality | 2 | partial | 7/10 | Xcommunity | |
Build against official SDKs in at least Python and TypeScript with equivalent memory APIs C Sdks | developer | Sdk integrations — stories about sdk integrations in this arenaSdk integrations | 2 | partial | 6/10 | Cclaimed | |
Control data retention and deletion G | ai-native user | Privacy posture — data-handling and privacy storiesPrivacy posture | 2 | partial | 6/10 | Cclaimed | |
Delete a user's memories on demand — single memory, per-entity, or full erasure — to satisfy privacy requirements C Forgetting | platform-engineer | Data lifecycle — stories about data lifecycle in this arenaData lifecycle | 2 | partial | 6/10 | Cclaimed | |
Do everything through the API that I can do in the UI G | ai-native user | Openness — open source, data portability, and self-hosting storiesOpenness | 2 | partial | 6/10 | Tprobed | |
Drop the memory layer into agent frameworks like LangChain, LangGraph, CrewAI, or the Vercel AI SDK via documented first-party integrations C Frameworks | developer | Sdk integrations — stories about sdk integrations in this arenaSdk integrations | 2 | partial | 6/10 | Cclaimed | |
Steer retrieval with metadata filters, keyword/hybrid search modes, or reranking instead of accepting a single fixed similarity search C Retrieval controls | developer | Memory recall quality — stories about memory recall quality in this arenaMemory recall quality | 2 | partial | 6/10 | Cclaimed | |
Rely on the memory layer to update, supersede, or merge memories when new information contradicts what was stored C Core memory | developer | Memory recall quality — stories about memory recall quality in this arenaMemory recall quality | 2 | partial | 5/10 | Cclaimed | |
Choose where my data is stored (region/residency) G | ai-native user | Privacy posture — data-handling and privacy storiesPrivacy posture | 2 | partial | 4/10 | Cclaimed | |
Govern who and what can read or write memory with roles, policies, or access-control lists, and audit that access C Governance | platform-engineer | Tenancy permissions — stories about tenancy permissions in this arenaTenancy permissions | 2 | partial | 4/10 | Cclaimed | |
Read the product's source under an open license G | ai-native user | Openness — open source, data portability, and self-hosting storiesOpenness | 2 | partial | 4/10 | Cclaimed | |
Retrieve a token-budgeted, prompt-ready context block assembled from relevant memories in one call C Context assembly | developer | Session context — stories about session context in this arenaSession context | 2 | partial | 4/10 | Cclaimed | |
Track when facts became valid or invalid (temporal reasoning) so the memory distinguishes current from outdated information C Knowledge graph | ml-engineer | Graph entity memory — stories about graph entity memory in this arenaGraph entity memory | 2 | partial | 4/10 | Cclaimed | |
Perform bulk operations across many items at once G | ai-native user | Automation depth — how much of the product can run unattendedAutomation depth | 2 | partial | 3/10 | Cclaimed | |
Ingest at scale with async or batch processing and check the status of background memory operations C Scale | platform-engineer | Retrieval performance — stories about retrieval performance in this arenaRetrieval performance | 2 | none | 0/10 | ||
Ingest documents, JSON, and business data into memory — not just chat transcripts C Ingestion | developer | Session context — stories about session context in this arenaSession context | 2 | none | 0/10 | ||
Opt out of telemetry and usage tracking G | ai-native user | Privacy posture — data-handling and privacy storiesPrivacy posture | 2 | none | untested | none yet | |
Schedule recurring jobs or workflows G | ai-native user | Automation depth — how much of the product can run unattendedAutomation depth | 2 | n/a | untested | none yet | |
See documented retrieval-latency targets or measured numbers (e.g. p50/p95) backing the product's speed claims C Latency | platform-engineer | Retrieval performance — stories about retrieval performance in this arenaRetrieval performance | 2 | none | untested | none yet | |
See published memory-quality benchmark results (e.g. LongMemEval, LoCoMo) backing the product's recall-accuracy claims C Benchmarks | ml-engineer | Memory recall quality — stories about memory recall quality in this arenaMemory recall quality | 2 | none | untested | none yet | |
See published pricing with a free tier and per-unit rates so I can project memory costs before committing G Pricing | platform-engineer | Pricing plans — plan structure and value — what each tier costs and what it unlocksPricing plans | 2 | none | untested | none yet | |
Run the memory layer fully locally — embedded in-process or against local models — without any cloud dependency C Self host | developer | Deployment self host — stories about deployment self host in this arenaDeployment self host | 1 | partial | 5/10 | Cclaimed | |
Share selected memory across multiple agents or users (team or group memory) while keeping private memory private C Sharing | developer | Tenancy permissions — stories about tenancy permissions in this arenaTenancy permissions | 1 | partial | 5/10 | Cclaimed | |
Customize the memory schema — entity types, edge types, or ontology — to match my domain C Schema customization | ml-engineer | Graph entity memory — stories about graph entity memory in this arenaGraph entity memory | 1 | none | 0/10 | ||
Store images, PDFs, or other files as memory inputs and recall information from them later C Ingestion | developer | Session context — stories about session context in this arenaSession context | 1 | none | 0/10 | ||
Wire memory into real-time voice pipelines (e.g. LiveKit, Pipecat, ElevenLabs) with documented integrations fast enough for live conversation C Frameworks | developer | Sdk integrations — stories about sdk integrations in this arenaSdk integrations | 1 | none | 0/10 | ||
Version, review, and roll back my automations G | ai-native user | Automation depth — how much of the product can run unattendedAutomation depth | 1 | n/a | untested | none yet |
Opportunities — the stories that would move this product's scores, from its own judged verdictsOpportunitiestop 8 of 35 stories with headroom
What would move Mem0’s scores — derived from its own judged verdicts, biggest headroom first. Each line quotes what the judge found missing; shipping it (or evidencing it publicly) is the fix.
Privacy posture — data-handling and privacy storiesPrevent my data from being used to train AI models
nonemoves PA Scoreimpact 30
No evidence anywhere in the pack addresses opting out of AI-model-training use of data, data-training policies, or contractual/privacy commitments about training; the docs focus entirely on memory storage/retrieval features.
Agenticness — how well agents can access and operate the productRely on versioned APIs with a documented deprecation policy
nonemoves API qualityimpact 30
The evidence pack shows quickstart docs, an OpenAPI spec, and various feature docs, but nothing about API versioning scheme or a documented deprecation policy.
Retrieval performance — stories about retrieval performance in this arenaIngest at scale with async or batch processing and check the status of background memory operations
nonemoves PA Scoreimpact 20
The evidence pack shows single add/search operations, CLI, webhooks, and quickstart flows, but nothing about async/batch ingestion APIs or a way to poll/check status of background memory operations.
Session context — stories about session context in this arenaIngest documents, JSON, and business data into memory — not just chat transcripts
nonemoves PA Scoreimpact 20
All evidence describes Mem0's add/search API in terms of conversation messages (client.add(messages, user_id=...)) and fact extraction from chat turns; there is no mention of ingesting documents, PDFs, JSON payloads, or arbitrary business data as a memory source.
Retrieval performance — stories about retrieval performance in this arenaSee documented retrieval-latency targets or measured numbers (e.g. p50/p95) backing the product's speed claims
nonemoves PA Scoreimpact 20
No evidence pack items mention latency numbers, p50/p95 metrics, or any documented performance/speed targets for retrieval; docs focus on features (search, graph memory, reranking) but never quantify speed.
Privacy posture — data-handling and privacy storiesOpt out of telemetry and usage tracking
nonemoves PA Scoreimpact 20
No evidence in the pack discusses telemetry, usage tracking, or any opt-out/privacy configuration setting for Mem0; the docs cover memory features, self-hosting, MCP, and CLI but never mention telemetry controls.
Memory recall quality — stories about memory recall quality in this arenaSee published memory-quality benchmark results (e.g. LongMemEval, LoCoMo) backing the product's recall-accuracy claims
nonemoves PA Scoreimpact 20
Missing: any benchmark citation, LongMemEval/LoCoMo results, accuracy/recall metrics, third-party evaluation.
Pricing plans — plan structure and value — what each tier costs and what it unlocksSee published pricing with a free tier and per-unit rates so I can project memory costs before committing
nonemoves PA Scoreimpact 20
No evidence in the pack mentions pricing, free tier, or per-unit rates anywhere in the docs, community, or probes; all citations concern product features (memory ops, MCP, CLI, graph memory) rather than pricing plans.
Showing the top 8 of 35 — every none/partial verdict in the story verdicts table is headroom.
Think a verdict is wrong? Every verdicts-table row has a Flag link — see the methodology.
Coverage map — which docs area, API section, or community source covers which judged storiesCoverage map7 surfaces · 40 covered stories
Where the cited evidence behind each covered verdict came from — the same citations the verdicts table shows, no extra judging.
Platform docs34 stories
- Point an agent at llms.txt or agent-oriented docs
- Run the product headlessly / in CI for automation
- Connect an agent via an official MCP server
- Use an official CLI
- Drive the product through a documented public API
- Issue scoped/least-privilege API credentials for an agent
- Build against official SDKs
- Subscribe to events via webhooks
- Get AI-generated insights and suggestions from my data inside the product
- Operate the product with natural-language commands
- Explore an interactive API reference with runnable examples
- Download a machine-readable API spec (OpenAPI or equivalent)
- Perform bulk operations across many items at once
- Define rules that trigger actions automatically on events
- Delete a user's memories on demand — single memory, per-entity, or full erasure — to satisfy privacy requirements
- Make memories expire or decay — via TTL, expiration dates, or recency weighting — so stale facts stop surfacing
- Export memories in a machine-readable format so the memory store is portable and not a lock-in trap
- Store memories as a knowledge graph of entities and relationships so multi-hop and entity-centric questions are answerable
- Track when facts became valid or invalid (temporal reasoning) so the memory distinguishes current from outdated information
- My agent can manage its own memory mid-conversation — adding, searching, updating, and deleting memories through tools or API calls it invokes itself
- The memory layer decides for itself what is worth remembering — extracting salient facts from raw conversation and consolidating them in the background
- Add memories from conversations and retrieve them later with semantic search, so context persists across sessions
- Rely on the memory layer to update, supersede, or merge memories when new information contradicts what was stored
- Steer retrieval with metadata filters, keyword/hybrid search modes, or reranking instead of accepting a single fixed similarity search
- Do everything through the API that I can do in the UI
- Export all of my data in open formats and leave
- Control data retention and deletion
- Connect off-the-shelf assistants (Claude, ChatGPT, Cursor) to the same memory so every tool I use shares what it knows about me
- Build against official SDKs in at least Python and TypeScript with equivalent memory APIs
- Retrieve a token-budgeted, prompt-ready context block assembled from relevant memories in one call
- Get summaries of past sessions or threads so an agent can pick up where the last conversation left off
- Govern who and what can read or write memory with roles, policies, or access-control lists, and audit that access
- Scope memories per user, agent, or application so one tenant's memories never leak into another's retrieval
- Share selected memory across multiple agents or users (team or group memory) while keeping private memory private
Open source docs12 stories
- Run the product headlessly / in CI for automation
- Issue scoped/least-privilege API credentials for an agent
- Export memories in a machine-readable format so the memory store is portable and not a lock-in trap
- Run the memory layer fully locally — embedded in-process or against local models — without any cloud dependency
- Self-host the memory layer from open-source code (e.g. via Docker) on infrastructure I control
- Do everything through the API that I can do in the UI
- Export all of my data in open formats and leave
- Read the product's source under an open license
- Self-host the core product
- Choose where my data is stored (region/residency)
- Control data retention and deletion
- Govern who and what can read or write memory with roles, policies, or access-control lists, and audit that access
docs.mem0.ai8 stories
- Run the product headlessly / in CI for automation
- Drive the product through a documented public API
- Build against official SDKs
- Explore an interactive API reference with runnable examples
- Download a machine-readable API spec (OpenAPI or equivalent)
- Connect off-the-shelf assistants (Claude, ChatGPT, Cursor) to the same memory so every tool I use shares what it knows about me
- Drop the memory layer into agent frameworks like LangChain, LangGraph, CrewAI, or the Vercel AI SDK via documented first-party integrations
- Build against official SDKs in at least Python and TypeScript with equivalent memory APIs
OpenAPI spec7 stories
- Point an agent at llms.txt or agent-oriented docs
- Run the product headlessly / in CI for automation
- Drive the product through a documented public API
- Build against official SDKs
- Explore an interactive API reference with runnable examples
- Download a machine-readable API spec (OpenAPI or equivalent)
- Do everything through the API that I can do in the UI
Core concepts docs7 stories
- Operate the product with natural-language commands
- My agent can manage its own memory mid-conversation — adding, searching, updating, and deleting memories through tools or API calls it invokes itself
- The memory layer decides for itself what is worth remembering — extracting salient facts from raw conversation and consolidating them in the background
- Add memories from conversations and retrieve them later with semantic search, so context persists across sessions
- Steer retrieval with metadata filters, keyword/hybrid search modes, or reranking instead of accepting a single fixed similarity search
- Retrieve a token-budgeted, prompt-ready context block assembled from relevant memories in one call
- Get summaries of past sessions or threads so an agent can pick up where the last conversation left off
llms.txt2 stories
Probe proofs — replayable recordings from the probe harnessProbe proofs
Replayable recordings from our probe harness — see the Prove-It protocol to submit one.
$uvx --from mem0-cli mem0 --helpreproduced$ uvx --from mem0-cli mem0 --help ⠋ Resolving dependencies... ⠙ Resolving dependencies... ⠋ Resolving dependencies... ⠙ Resolving dependencies... ⠙ mem0-cli==0.2.12 ⠙ httpx==0.28.1 ⠙ rich==15.0.0 ⠙ typer==0.27.2 ⠙ anyio==4.15.0 ⠙ certifi==2026.7.22 ⠙ httpcore==1.0.9 ⠙ idna==3.19 ⠙ markdown-it-py==4.2.0 ⠙ pygments==2.21.0 ⠙ shellingham==1.5.4 ⠙ annotated-doc==0.0.5 ⠙ typing-extensions==4.16.0 ⠙ typing-extensions==4.16.0 ⠙ h11==0.16.0 ⠙ mdurl==0.1.2 ⠙ Usage: mem0 <command> [options] ◆ Mem0 CLI v0.2.12 · Python SDK The Memory Layer for AI Agents ╭─ Options ────────────────────────────────────────────────────────────────────╮ │ --version Show version and exit. │ │ --json,--agent Output as JSON for agent/programmatic use. │ │ --help Show this message and exit. │ ╰──────────────────────────────────────────────────────────────────────────────╯ ╭─ Memory ─────────────────────────────────────────────────────────────────────╮ │ add Add a memory from text, messages, file, or stdin. │ │ search Query your memory store — semantic, [redacted]word, or hybrid │ │ retrieval. │ │ get Get a specific memory by ID. │ │ list List memories with optional filters. │ │ update Update a memory's text or metadata. │ │ delete Delete a memory, all memories, or an entity. │ ╰──────────────────────────────────────────────────────────────────────────────╯ ╭─ Management ─────────────────────────────────────────────────────────────────╮ │ init Interactive setup wizard for mem0 CLI. │ │ status Check connectivity and authentication. │ │ version Show version and exit. │ │ import Import memories from a JSON file. │ │ help Show help. Use --json for machine-readable output (for LLM │ │ agents). │ │ entity Manage entities. │ │ event Inspect background processing events. │ │ config Manage mem0 configuration. │ ╰──────────────────────────────────────────────────────────────────────────────╯ ╭─ Setup ──────────────────────────────────────────────────────────────────────╮ │ identify Tag your active Agent Mode [redacted] with the AI agent that's using │ │ it. │ │ whoami Print your AGENTRUSH identifier (default_user_id). │ │ agent-rush AGENTRUSH game commands │ ╰──────────────────────────────────────────────────────────────────────────────╯
$curl -si -X POST https://mcp.mem0.ai/mcp/ -H 'Content-Type: application/json' -d '<jsonrpc initialize>'reproduced$ curl -si -X POST https://mcp.mem0.ai/mcp/ -H 'Content-Type: application/json' -d '<jsonrpc initialize>'
HTTP/2 401
date: Sat, 05 Sep 2026 00:46:49 GMT
content-type: application/json
content-length: 74
server: cloudflare
www-authenticate: Bearer error="invalid_[redacted]", error_description="Authentication required", resource_metadata="https://mcp.mem0.ai/.well-known/oauth-protected-resource"
cf-cache-status: DYNAMIC
report-to: {"group":"cf-nel","max_age":604800,"endpoints":[{"url":"https://a.nel.cloudflare.com/report/v4?s=9Q2wXp7tke9ruAkYblh0c4wGH5MlwpBKA2H6lIK%2FXIR28ldX7AOvm1cYk9kVJQqN4k%2F50V9M1duc2OcT5O%2F6YJUKZnBkPiHqKflQXytCHXJ0iFm1M2kQKTjwGok6"}]}
nel: {"report_to":"cf-nel","success_fraction":0.0,"max_age":604800}
cf-ray: a361381978c136e8-SJC
{"error": "invalid_[redacted]", "error_description": "Authentication required"}
$uv run --with mem0ai python3 -c 'import mem0; from mem0 import Memory; print("PA_PROBE_OK mem0ai", mem0.__version__)'reproduced$ uv run --with mem0ai python3 -c 'import mem0; from mem0 import Memory; print("PA_PROBE_OK mem0ai", mem0.__version__)'
⠋ Resolving dependencies...
⠙ Resolving dependencies...
⠋ Resolving dependencies...
⠙ Resolving dependencies...
⠙ mem0ai==2.0.20
⠙ httpx==0.28.1
⠙ openai==3.8.0
⠙ posthog==7.47.0
⠙ protobuf==6.33.6
⠙ pydantic==2.13.5
⠙ pydantic-core==2.46.5
⠙ pytz==2026.3.post1
⠙ qdrant-client==1.19.0
⠙ httpx==0.28.1
⠙ sqlalchemy==2.0.52
⠙ anyio==4.15.0
⠙ certifi==2026.7.22
⠙ httpcore==1.0.9
⠙ idna==3.19
⠙ httpx2==2.12.0
⠙ httpcore2==2.12.0
⠙ httpcore2==2.12.0
PA_PROBE_OK mem0ai 2.0.20
Claims vs evidence — vendor claims reconciled against independent verdictsClaims vs evidence
6 of 18 testable claims verified · 0 contradicted → integrity 33/100
19 distinct capability claims found in Mem0’s own claimed-docs/GitHub materials, reconciled against our judge’s independent verdicts.
6
Verified
12
Unverified
0
Contradicted
22
Undersold
Verified (10)
“Quickstart lets you get an API key and store/search your first memory within minutes”
Add memories from conversations and retrieve them later with semantic search, so context persists across sessionsfullproof ↗
“MCP server exposes memory tools so an agent can autonomously save, look up, or update its own memories”
“MCP server exposes memory tools so an agent can autonomously save, look up, or update its own memories”
My agent can manage its own memory mid-conversation — adding, searching, updating, and deleting memories through tools or API calls it invokes itselffullproof ↗
“A coding agent can create its own account and API key from the terminal with a few commands, no email or dashboard needed”
“Natural-language search lets agents query stored memories and get back the most relevant ones”
Add memories from conversations and retrieve them later with semantic search, so context persists across sessionsfullproof ↗
“Official CLI supports adding, searching, listing, updating, and deleting memories directly from the terminal”
“Plugins let coding tools like Claude Code, Cursor, and Codex remember project context via shared memory”
Connect off-the-shelf assistants (Claude, ChatGPT, Cursor) to the same memory so every tool I use shares what it knows about mefullproof ↗
“Any AI client can be connected to Mem0 via the Model Context Protocol in minutes”
“Mem0 automatically extracts individual facts from a conversation and stores each one separately”
The memory layer decides for itself what is worth remembering — extracting salient facts from raw conversation and consolidating them in the backgroundpartialproof ↗
“SDK provides a simple add call (e.g. client.add(messages, user_id=...)) for storing conversation memories per user”
Add memories from conversations and retrieve them later with semantic search, so context persists across sessionsfullproof ↗
Unverified (14)
“A coding agent can create its own account and API key from the terminal with a few commands, no email or dashboard needed”
Issue scoped/least-privilege API credentials for an agentpartialproof ↗
“Open-source version runs the same memory engine on your own infrastructure, giving full ownership of stack and data”
Self-host the memory layer from open-source code (e.g. via Docker) on infrastructure I controlfullproof ↗
“Open-source version runs the same memory engine on your own infrastructure, giving full ownership of stack and data”
“Self-hosted Docker bundle ships REST API, dashboard, per-user API keys, and a request audit log”
Govern who and what can read or write memory with roles, policies, or access-control lists, and audit that accesspartialproof ↗
“Self-hosted Docker bundle ships REST API, dashboard, per-user API keys, and a request audit log”
Self-host the memory layer from open-source code (e.g. via Docker) on infrastructure I controlfullproof ↗
“Platform automatically builds a native graph linking people, places and concepts from memories, with no external graph database to run”
Store memories as a knowledge graph of entities and relationships so multi-hop and entity-centric questions are answerablefullproof ↗
“Memories can be scoped separately per user, agent, and application so retrieval stays isolated per tenant”
Scope memories per user, agent, or application so one tenant's memories never leak into another's retrievalfullproof ↗
“Reranking step reorders search results using deep semantic understanding to surface the most relevant memories first”
Steer retrieval with metadata filters, keyword/hybrid search modes, or reranking instead of accepting a single fixed similarity searchpartialproof ↗
“Setting an expiration_date on a memory stops it from being surfaced in search after that date, without deleting it”
Make memories expire or decay — via TTL, expiration dates, or recency weighting — so stale facts stop surfacingfullproof ↗
“Memory Export feature creates structured exports of memories using customizable Pydantic schemas”
Export memories in a machine-readable format so the memory store is portable and not a lock-in trapfullproof ↗
“Webhooks send real-time HTTP notifications when memories are created, updated, deleted, or categorized”
“Documented setup guides cover 22 integrations including LangChain, CrewAI, LlamaIndex, and the Vercel AI SDK”
Drop the memory layer into agent frameworks like LangChain, LangGraph, CrewAI, or the Vercel AI SDK via documented first-party integrationspartialproof ↗
“SDK provides a simple add call (e.g. client.add(messages, user_id=...)) for storing conversation memories per user”
Build against official SDKs in at least Python and TypeScript with equivalent memory APIspartialproof ↗
“Users can ask entity-centric questions (e.g. 'what do we know about Alice') and get facts pulled from many past conversations”
Store memories as a knowledge graph of entities and relationships so multi-hop and entity-centric questions are answerablefullproof ↗
Undersold (22)
Point an agent at llms.txt or agent-oriented docsfullproof ↗
Run the product headlessly / in CI for automationfullproof ↗
Drive the product through a documented public APIfullproof ↗
Get AI-generated insights and suggestions from my data inside the productpartialproof ↗
Operate the product with natural-language commandspartialproof ↗
Explore an interactive API reference with runnable examplespartialproof ↗
Download a machine-readable API spec (OpenAPI or equivalent)fullproof ↗
Perform bulk operations across many items at oncepartialproof ↗
Define rules that trigger actions automatically on eventspartialproof ↗
Delete a user's memories on demand — single memory, per-entity, or full erasure — to satisfy privacy requirementspartialproof ↗
Run the memory layer fully locally — embedded in-process or against local models — without any cloud dependencypartialproof ↗
Track when facts became valid or invalid (temporal reasoning) so the memory distinguishes current from outdated informationpartialproof ↗
Rely on the memory layer to update, supersede, or merge memories when new information contradicts what was storedpartialproof ↗
Do everything through the API that I can do in the UIpartialproof ↗
Export all of my data in open formats and leavepartialproof ↗
Read the product's source under an open licensepartialproof ↗
Choose where my data is stored (region/residency)partialproof ↗
Retrieve a token-budgeted, prompt-ready context block assembled from relevant memories in one callpartialproof ↗
Get summaries of past sessions or threads so an agent can pick up where the last conversation left offpartialproof ↗
Share selected memory across multiple agents or users (team or group memory) while keeping private memory privatepartialproof ↗
Business model
Apache-2.0 open-source core; managed Platform has a free tier, then usage-priced Starter/Pro plans by memory operations and retrievals, plus custom enterprise.
pricing ↗Score trend
How this product’s scores have moved as evidence and verdicts are re-derived — a point per change, not per day.
Try Experimental
Run it in the microterminal →Recorded agent sessions — and a live MCP handshake where the vendor ships one.
Flag
⚑ Flag a verdictThink a verdict is wrong? Opens a prefilled GitHub issue — or use the ⚑ next to any verdict above.
For agents
Agent surface uptime MCP 100% · llms.txt 100% · openapi.json 100% (30d, checked every 6h since Sep 8 '26)