Rank #4 of 7 in Browser Automation for Agents
Access
 vs Browser Use
 vs Skyvern
 vs Hyperbrowser
 vs Steel
 vs Notte
 vs Smooth
Showcase
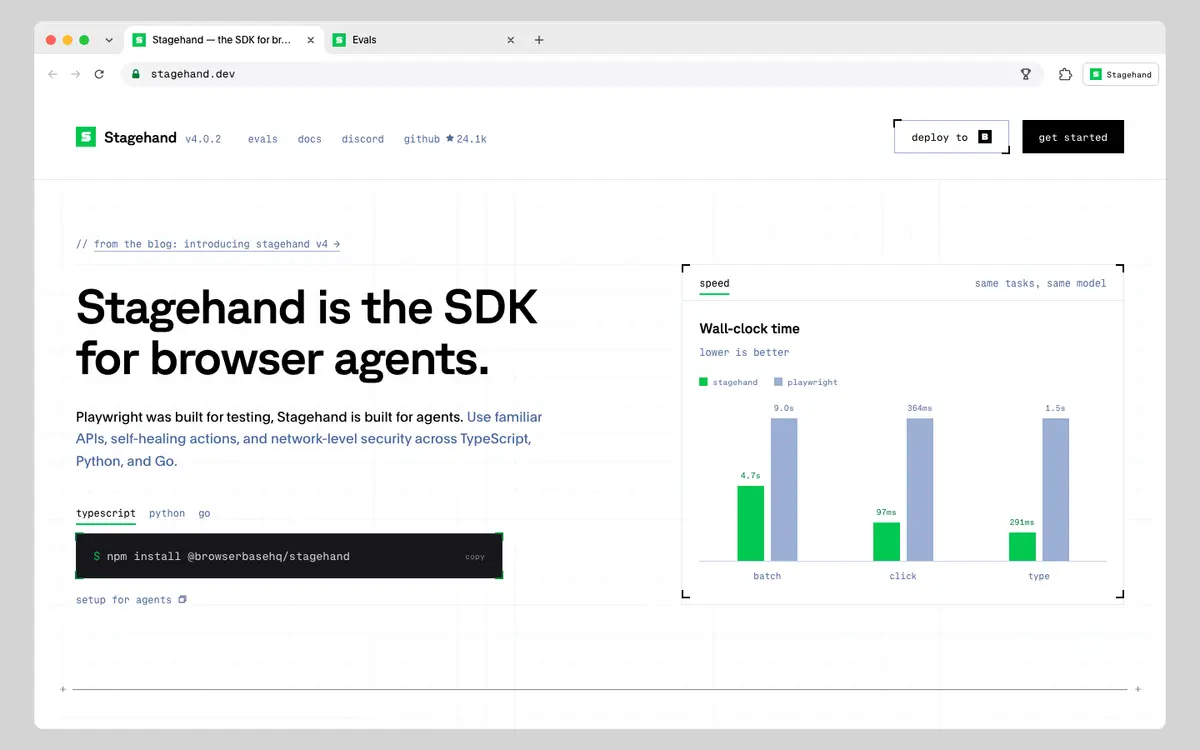
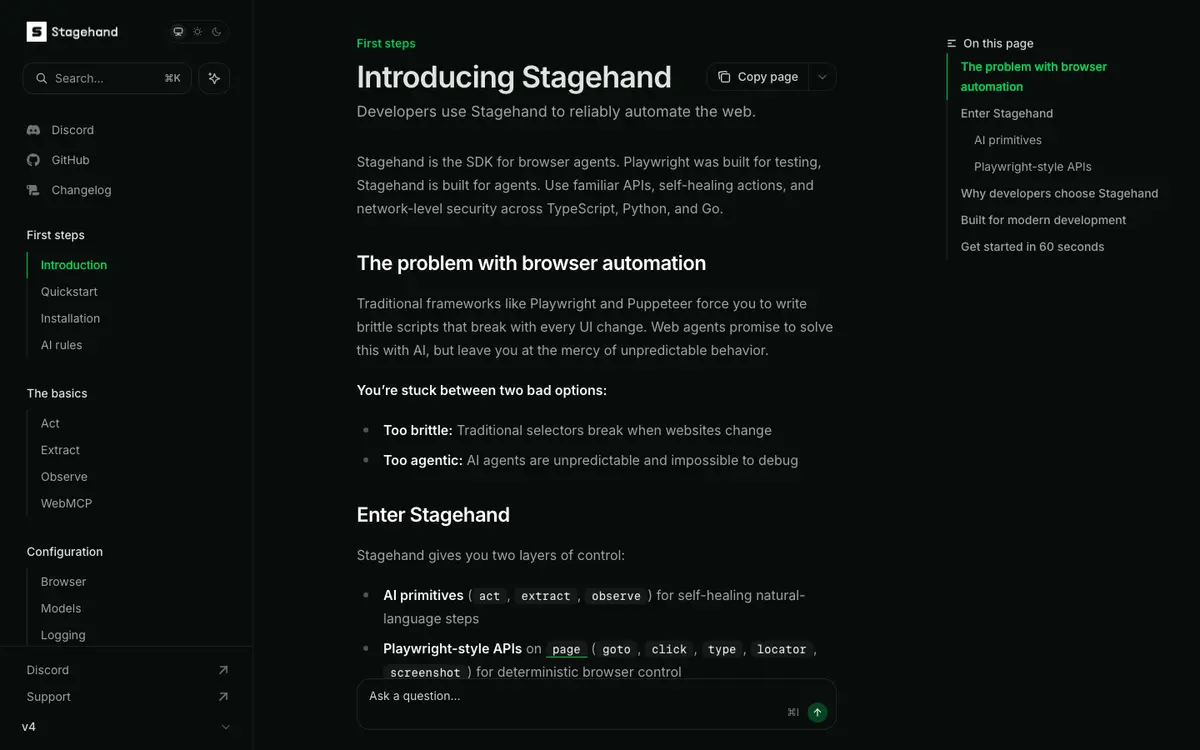
Browserbase ships more than one product — each judged line competes in its own arena on the same stories as everyone else.
| Line | Arena | Rank | PA Score | Agent-ready |
|---|---|---|---|---|
| Browserbase | Web Scraping APIs | #5/8 | 27/100 | 58/100 |
| Stagehandthis page | Browser Automation for Agents | #4/7 | 28/100 | 51/100 |
Try itExperimental
See what an agent can do with Stagehand before you ever sign up. Pick a story: recorded sessions replay real probe-harness transcripts; sandboxed self-drive sessions are designed and gated (docs/TRY-IT.md).
$echo '<jsonrpc initialize>' | npx -y @browserbasehq/mcprecorded session — replayed, not liveVerified integrations
Connections to other tracked products — hover a chip for the verbatim evidence quote behind it.


By theme — the product's score on each story themeBy theme
Action primitives — stories about action primitives in this arenaAction primitivesevidence →
Stories about action primitives in this arena
Agenticness — how well agents can access and operate the productAgenticnessevidence →
How well agents can access and operate the product
Auth session persistence — stories about auth session persistence in this arenaAuth session persistenceevidence →
Stories about auth session persistence in this arena
Automation depth — how much of the product can run unattendedAutomation depthevidence →
How much of the product can run unattended
Deployment modes — stories about deployment modes in this arenaDeployment modesevidence →
Stories about deployment modes in this arena
Framework model support — stories about framework model support in this arenaFramework model supportevidence →
Stories about framework model support in this arena
Nl task execution — stories about nl task execution in this arenaNl task executionevidence →
Stories about nl task execution in this arena
Openness — open source, data portability, and self-hosting storiesOpennessevidence →
Open source, data portability, and self-hosting stories
Pricing limits — free-tier ceilings, usage caps, and rate limits before you have to payPricing limitsevidence →
Free-tier ceilings, usage caps, and rate limits before you have to pay
Privacy posture — data-handling and privacy storiesPrivacy postureevidence →
Data-handling and privacy stories
Replay debugging — stories about replay debugging in this arenaReplay debuggingevidence →
Stories about replay debugging in this arena
Scale parallelism — running many jobs at once — concurrency, fleets, queueingScale parallelismevidence →
Running many jobs at once — concurrency, fleets, queueing
Stealth captcha — stories about stealth captcha in this arenaStealth captchaevidence →
Stories about stealth captcha in this arena
Structured extraction — stories about structured extraction in this arenaStructured extractionevidence →
Stories about structured extraction in this arena
Story verdicts — every judged story with its evidenceStory verdicts
Follow the green: where the map greys out is where Stagehand stops today. ✓ full · ~ partial · ! disputed · — none · n/a not applicable.
Action primitives — stories about action primitives in this arenaAction primitives
Stories about action primitives in this arena
Cache resolved actions or generated code so repeat runs replay deterministically at lower cost and latency than re-prompting the LLM
✓7/10
Drive the page through DOM-understanding action primitives (act/click/type on described elements) that survive selector and layout changes
✓8/10
Preview candidate actions on the current page (observe/plan) before committing the agent to act
✓8/10
Switch to a vision or computer-use action mode that operates on screenshots for canvases and UIs the DOM path can't handle
—0/10
Agenticness — how well agents can access and operate the productAgenticness
How well agents can access and operate the product
API surface
Drive the product through a documented public API
✓8/10
unlocks → Scoped API keys · Machine-readable spec · Versioning policy · API sandbox · Official CLI · Full data export · Submit a browser task over a hosted HTTP API and receive the result by polling or webhook, without managing any browser myself
Subscribe to events via webhooks
n/an/a
Build against official SDKs
✓8/10
Issue scoped/least-privilege API credentials for an agent
—0/10
Connect an agent via an official MCP server
✓8/10
Download a machine-readable API spec (OpenAPI or equivalent)
—0/10
Rely on versioned APIs with a documented deprecation policy
—0/10
Test against a sandbox environment without touching production data
—–
Explore an interactive API reference with runnable examples
—0/10
Agentic features
Delegate tasks to a built-in AI assistant inside the product
✓8/10
unlocks → MCP client
Operate the product with natural-language commands
✓9/10
Plug MCP servers into this product so it can use their tools
—0/10
Get AI-generated insights and suggestions from my data inside the product
n/an/a
Set up automations that run autonomously in the background
~5/10
Auth session persistence — stories about auth session persistence in this arenaAuth session persistence
Stories about auth session persistence in this arena
Connect my existing Playwright, Puppeteer, or CDP automation code to the product's browsers instead of rewriting it
~6/10
Store credentials in a vault and have the agent complete logins including TOTP/2FA challenges without exposing secrets to the model
—0/10
Persist logged-in browser state in reusable profiles so agents skip the login wall on every subsequent run
✓8/10
Automation depth — how much of the product can run unattendedAutomation depth
How much of the product can run unattended
Deployment modes — stories about deployment modes in this arenaDeployment modes
Stories about deployment modes in this arena
Framework model support — stories about framework model support in this arenaFramework model support
Stories about framework model support in this arena
Nl task execution — stories about nl task execution in this arenaNl task execution
Stories about nl task execution in this arena
Openness — open source, data portability, and self-hosting storiesOpenness
Open source, data portability, and self-hosting stories
Pricing limits — free-tier ceilings, usage caps, and rate limits before you have to payPricing limits
Free-tier ceilings, usage caps, and rate limits before you have to pay
Privacy posture — data-handling and privacy storiesPrivacy posture
Data-handling and privacy stories
Replay debugging — stories about replay debugging in this arenaReplay debugging
Stories about replay debugging in this arena
Scale parallelism — running many jobs at once — concurrency, fleets, queueingScale parallelism
Running many jobs at once — concurrency, fleets, queueing
Stealth captcha — stories about stealth captcha in this arenaStealth captcha
Stories about stealth captcha in this arena
Rely on a documented captcha stance — automatic solving, human fallback, or explicit non-support — instead of silent task failures
~3/10
Point to the vendor's published acceptable-use and anti-abuse posture governing what its stealth and automation features may be used for
—–
Enable stealth fingerprinting and residential or geo-targeted proxies so legitimate automations aren't blocked as bots
~5/10
Structured extraction — stories about structured extraction in this arenaStructured extraction
Stories about structured extraction in this arena
Sorted by importance (agentic first) (high → low) · 52/52 stories · click a row’s chevron for the rationale and evidence
Connect an agent via an official MCP server G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 3 | full | 8/10 | Tprobed | |
Delegate tasks to a built-in AI assistant inside the product G Agentic features | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 3 | full | 8/10 | Xcommunity | |
Drive the product through a documented public API G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 3 | full | 8/10 | Tprobed | |
Plug MCP servers into this product so it can use their tools G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 3 | none | 0/10 | ||
Operate the product with natural-language commands G Agentic features | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | full | 9/10 | Xcommunity | |
Build against official SDKs G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | full | 8/10 | Tprobed | |
Point an agent at llms.txt or agent-oriented docs G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | full | 8/10 | Tprobed | |
Run the product headlessly / in CI for automation G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | full | 8/10 | Tprobed | |
Set up automations that run autonomously in the background G Agentic features | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | partial | 5/10 | Cclaimed | |
Download a machine-readable API spec (OpenAPI or equivalent) G Api quality | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | none | 0/10 | ||
Explore an interactive API reference with runnable examples G Api quality | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | none | 0/10 | ||
Issue scoped/least-privilege API credentials for an agent G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | none | 0/10 | ||
Rely on versioned APIs with a documented deprecation policy G Api quality | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | none | 0/10 | ||
Use an official CLI G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | none | 0/10 | ||
Get AI-generated insights and suggestions from my data inside the product G Agentic features | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | n/a | untested | none yet | |
Subscribe to events via webhooks G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | n/a | untested | none yet | |
Test against a sandbox environment without touching production data G Api quality | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 1 | none | untested | none yet | |
Drive the page through DOM-understanding action primitives (act/click/type on described elements) that survive selector and layout changes C Dom | developer | Action primitives — stories about action primitives in this arenaAction primitives | 3 | full | 8/10 | Xcommunity | |
Persist logged-in browser state in reusable profiles so agents skip the login wall on every subsequent run C Profiles | developer | Auth session persistence — stories about auth session persistence in this arenaAuth session persistence | 3 | full | 8/10 | Cclaimed | |
Extract typed, schema-validated data (Zod/Pydantic-style) from pages the agent visits, not just raw text C Extraction | developer | Structured extraction — stories about structured extraction in this arenaStructured extraction | 3 | full | 7/10 | Cclaimed | |
Self-host the core product G | ai-native user | Openness — open source, data portability, and self-hosting storiesOpenness | 3 | partial | 6/10 | Tprobed | |
Hand the product a natural-language goal and it completes a multi-step web task end to end — navigating, filling forms, and clicking through flows C Tasks | developer | Nl task execution — stories about nl task execution in this arenaNl task execution | 3 | partial | 5/10 | Xcommunity | |
Define rules that trigger actions automatically on events G | ai-native user | Automation depth — how much of the product can run unattendedAutomation depth | 3 | none | untested | none yet | |
Export all of my data in open formats and leave G | ai-native user | Openness — open source, data portability, and self-hosting storiesOpenness | 3 | none | untested | none yet | |
Prevent my data from being used to train AI models G | ai-native user | Privacy posture — data-handling and privacy storiesPrivacy posture | 3 | none | untested | none yet | |
Cache resolved actions or generated code so repeat runs replay deterministically at lower cost and latency than re-prompting the LLM C Caching | developer | Action primitives — stories about action primitives in this arenaAction primitives | 2 | full | 7/10 | Cclaimed | |
Run the agent against a local browser on my own machine for development, without any cloud account C Local | developer | Deployment modes — stories about deployment modes in this arenaDeployment modes | 2 | full | 7/10 | Cclaimed | |
Choose where my data is stored (region/residency) G | ai-native user | Privacy posture — data-handling and privacy storiesPrivacy posture | 2 | partial | 6/10 | Cclaimed | |
Connect my existing Playwright, Puppeteer, or CDP automation code to the product's browsers instead of rewriting it C Compat | developer | Auth session persistence — stories about auth session persistence in this arenaAuth session persistence | 2 | partial | 6/10 | Xcommunity | |
Compose repeatable multi-step workflows with loops, conditionals, and parameters instead of one-shot prompts C Workflows | automation-engineer | Nl task execution — stories about nl task execution in this arenaNl task execution | 2 | partial | 5/10 | Cclaimed | |
Debug a failed agent run from recorded replays — video, screenshots, step-by-step action timelines C Replay | automation-engineer | Replay debugging — stories about replay debugging in this arenaReplay debugging | 2 | partial | 5/10 | Cclaimed | |
Enable stealth fingerprinting and residential or geo-targeted proxies so legitimate automations aren't blocked as bots C Stealth | automation-engineer | Stealth captcha — stories about stealth captcha in this arenaStealth captcha | 2 | partial | 5/10 | Xcommunity | |
Plug the browser layer into agent frameworks (Claude Agent SDK, Vercel AI SDK, LangChain, CrewAI) through documented adapters C Frameworks | developer | Framework model support — stories about framework model support in this arenaFramework model support | 2 | partial | 4/10 | Tprobed | |
Watch a session live and take human control mid-run when the agent gets stuck C Live | automation-engineer | Replay debugging — stories about replay debugging in this arenaReplay debugging | 2 | partial | 4/10 | Cclaimed | |
Rely on a documented captcha stance — automatic solving, human fallback, or explicit non-support — instead of silent task failures C Captcha | automation-engineer | Stealth captcha — stories about stealth captcha in this arenaStealth captcha | 2 | partial | 3/10 | Xcommunity | |
Bring my own LLM provider — the framework is model-agnostic rather than locked to one vendor's models C Models | developer | Framework model support — stories about framework model support in this arenaFramework model support | 2 | none | 0/10 | ||
Control data retention and deletion G | ai-native user | Privacy posture — data-handling and privacy storiesPrivacy posture | 2 | none | 0/10 | ||
Run a fleet of concurrent browser sessions with documented concurrency limits and programmatic session management C Fleets | automation-engineer | Scale parallelism — running many jobs at once — concurrency, fleets, queueingScale parallelism | 2 | none | 0/10 | ||
Store credentials in a vault and have the agent complete logins including TOTP/2FA challenges without exposing secrets to the model G Credentials | automation-engineer | Auth session persistence — stories about auth session persistence in this arenaAuth session persistence | 2 | none | 0/10 | ||
Submit a browser task over a hosted HTTP API and receive the result by polling or webhook, without managing any browser myself C Tasks | ai agent | Nl task execution — stories about nl task execution in this arenaNl task execution | 2 | none | 0/10 | ||
Switch to a vision or computer-use action mode that operates on screenshots for canvases and UIs the DOM path can't handle C Vision | developer | Action primitives — stories about action primitives in this arenaAction primitives | 2 | none | 0/10 | ||
Do everything through the API that I can do in the UI G | ai-native user | Openness — open source, data portability, and self-hosting storiesOpenness | 2 | n/a | untested | none yet | |
Opt out of telemetry and usage tracking G | ai-native user | Privacy posture — data-handling and privacy storiesPrivacy posture | 2 | none | untested | none yet | |
Perform bulk operations across many items at once G | ai-native user | Automation depth — how much of the product can run unattendedAutomation depth | 2 | none | untested | none yet | |
Read the product's source under an open license G | ai-native user | Openness — open source, data portability, and self-hosting storiesOpenness | 2 | none | untested | none yet | |
Schedule recurring jobs or workflows G | ai-native user | Automation depth — how much of the product can run unattendedAutomation depth | 2 | n/a | untested | none yet | |
See transparent per-task or per-browser-hour pricing and documented rate/concurrency limits before committing G Pricing | developer | Pricing limits — free-tier ceilings, usage caps, and rate limits before you have to payPricing limits | 2 | none | untested | none yet | |
Preview candidate actions on the current page (observe/plan) before committing the agent to act C Observe | developer | Action primitives — stories about action primitives in this arenaAction primitives | 1 | full | 8/10 | Tprobed | |
Get webhook notifications when tasks and sessions finish instead of polling for status C Lifecycle | developer | Scale parallelism — running many jobs at once — concurrency, fleets, queueingScale parallelism | 1 | none | untested | none yet | |
My agent can download files from and upload files to the sites it operates, with the artifacts retrievable afterwards C Files | developer | Structured extraction — stories about structured extraction in this arenaStructured extraction | 1 | none | untested | none yet | |
Point to the vendor's published acceptable-use and anti-abuse posture governing what its stealth and automation features may be used for C Posture | automation-engineer | Stealth captcha — stories about stealth captcha in this arenaStealth captcha | 1 | none | untested | none yet | |
Version, review, and roll back my automations G | ai-native user | Automation depth — how much of the product can run unattendedAutomation depth | 1 | n/a | untested | none yet |
Opportunities — the stories that would move this product's scores, from its own judged verdictsOpportunitiestop 8 of 34 stories with headroom
What would move Stagehand’s scores — derived from its own judged verdicts, biggest headroom first. Each line quotes what the judge found missing; shipping it (or evidencing it publicly) is the fix.
Agenticness — how well agents can access and operate the productPlug MCP servers into this product so it can use their tools
nonemoves agent-readyimpact 45
All evidence shows Stagehand exposing its own browser-automation tools via MCP (server role) to other agents like Claude Code, not Stagehand acting as an MCP client that consumes external MCP servers' tools.
Automation depth — how much of the product can run unattendedDefine rules that trigger actions automatically on events
nonemoves PA Scoreimpact 30
The evidence describes Stagehand's act/observe/extract primitives for executing AI-driven browser actions, caching, and self-healing selectors, but nothing about defining persistent rules that automatically trigger on events (e.g., webhooks, schedules, DOM-change listeners) outside of an explicit script invocation.
Openness — open source, data portability, and self-hosting storiesExport all of my data in open formats and leave
nonemoves PA Scoreimpact 30
The axis applies to this product kind (peer products hold positive or none verdicts on this story), so lack of evidence for an applicable capability is "none", never "na".
Privacy posture — data-handling and privacy storiesPrevent my data from being used to train AI models
nonemoves PA Scoreimpact 30
The axis applies to this product kind (peer products hold positive or none verdicts on this story), so lack of evidence for an applicable capability is "none", never "na".
Agenticness — how well agents can access and operate the productUse an official CLI
nonemoves agent-readyimpact 30
Stagehand is distributed as an npm SDK/library plus an MCP server; the evidence pack shows npm install and MCP server invocation via npx, but no dedicated official CLI tool for direct AI-native command-line interaction is documented anywhere.
Agenticness — how well agents can access and operate the productIssue scoped/least-privilege API credentials for an agent
nonemoves agent-readyimpact 30
Missing: any mention of scoped API key issuance, permission scoping, or least-privilege credential management for agents.
Agenticness — how well agents can access and operate the productExplore an interactive API reference with runnable examples
nonemoves API qualityimpact 30
The evidence pack shows standard prose documentation pages (docs.stagehand.dev) and confirms no OpenAPI/swagger spec exists (404s on all candidate paths), with no mention anywhere of an interactive, runnable-example API reference (e.g., live code sandbox or Swagger-style explorer).
Agenticness — how well agents can access and operate the productDownload a machine-readable API spec (OpenAPI or equivalent)
nonemoves API qualityimpact 30
Direct probes for OpenAPI/swagger specs at all standard paths returned 404, and no documentation mentions a downloadable machine-readable API spec; only an llms.txt exists which is not an API spec.
Showing the top 8 of 34 — every none/partial verdict in the story verdicts table is headroom.
Think a verdict is wrong? Every verdicts-table row has a Flag link — see the methodology.
Coverage map — which docs area, API section, or community source covers which judged storiesCoverage map5 surfaces · 24 covered stories
Where the cited evidence behind each covered verdict came from — the same citations the verdicts table shows, no extra judging.
V4 docs22 stories
- Cache resolved actions or generated code so repeat runs replay deterministically at lower cost and latency than re-prompting the LLM
- Drive the page through DOM-understanding action primitives (act/click/type on described elements) that survive selector and layout changes
- Preview candidate actions on the current page (observe/plan) before committing the agent to act
- Run the product headlessly / in CI for automation
- Connect an agent via an official MCP server
- Drive the product through a documented public API
- Build against official SDKs
- Set up automations that run autonomously in the background
- Delegate tasks to a built-in AI assistant inside the product
- Operate the product with natural-language commands
- Connect my existing Playwright, Puppeteer, or CDP automation code to the product's browsers instead of rewriting it
- Persist logged-in browser state in reusable profiles so agents skip the login wall on every subsequent run
- Run the agent against a local browser on my own machine for development, without any cloud account
- Plug the browser layer into agent frameworks (Claude Agent SDK, Vercel AI SDK, LangChain, CrewAI) through documented adapters
- Hand the product a natural-language goal and it completes a multi-step web task end to end — navigating, filling forms, and clicking through flows
- Compose repeatable multi-step workflows with loops, conditionals, and parameters instead of one-shot prompts
- Self-host the core product
- Choose where my data is stored (region/residency)
- Watch a session live and take human control mid-run when the agent gets stuck
- Debug a failed agent run from recorded replays — video, screenshots, step-by-step action timelines
- Enable stealth fingerprinting and residential or geo-targeted proxies so legitimate automations aren't blocked as bots
- Extract typed, schema-validated data (Zod/Pydantic-style) from pages the agent visits, not just raw text
Hacker News11 stories
- Drive the page through DOM-understanding action primitives (act/click/type on described elements) that survive selector and layout changes
- Run the product headlessly / in CI for automation
- Connect an agent via an official MCP server
- Drive the product through a documented public API
- Delegate tasks to a built-in AI assistant inside the product
- Operate the product with natural-language commands
- Connect my existing Playwright, Puppeteer, or CDP automation code to the product's browsers instead of rewriting it
- Plug the browser layer into agent frameworks (Claude Agent SDK, Vercel AI SDK, LangChain, CrewAI) through documented adapters
- Hand the product a natural-language goal and it completes a multi-step web task end to end — navigating, filling forms, and clicking through flows
- Rely on a documented captcha stance — automatic solving, human fallback, or explicit non-support — instead of silent task failures
- Enable stealth fingerprinting and residential or geo-targeted proxies so legitimate automations aren't blocked as bots
docs.stagehand.dev11 stories
- Drive the page through DOM-understanding action primitives (act/click/type on described elements) that survive selector and layout changes
- Preview candidate actions on the current page (observe/plan) before committing the agent to act
- Run the product headlessly / in CI for automation
- Drive the product through a documented public API
- Build against official SDKs
- Delegate tasks to a built-in AI assistant inside the product
- Operate the product with natural-language commands
- Connect my existing Playwright, Puppeteer, or CDP automation code to the product's browsers instead of rewriting it
- Run the agent against a local browser on my own machine for development, without any cloud account
- Hand the product a natural-language goal and it completes a multi-step web task end to end — navigating, filling forms, and clicking through flows
- Compose repeatable multi-step workflows with loops, conditionals, and parameters instead of one-shot prompts
llms.txt3 stories
Probe proofs — replayable recordings from the probe harnessProbe proofs
Replayable recordings from our probe harness — see the Prove-It protocol to submit one.
$echo '<jsonrpc initialize>' | npx -y @browserbasehq/mcpreproduced$ echo '<jsonrpc initialize>' | npx -y @browserbasehq/mcp
\|/Warning: BROWSERBASE_API_[redacted] environment variable not set. Using dummy value.
Warning: BROWSERBASE_PROJECT_ID environment variable not set. Using dummy value.
Warning: MODEL_API_[redacted] environment variable not set. Using dummy value.
{"result":{"protocolVersion":"2025-06-18","capabilities":{"resources":{"subscribe":true,"listChanged":true},"tools":{"listChanged":true}},"serverInfo":{"name":"Browserbase MCP Server","version":"3.0.0","description":"Cloud browser automation server powered by Browserbase and Stagehand. Enables LLMs to navigate websites, interact with elements, extract data, and capture screenshots using natural language commands.","capabilities":{"resources":{"subscribe":true,"listChanged":true},"tools":{}}}},"jsonrpc":"2.0","id":1}
\
$mktemp -d && npm install @browserbasehq/stagehand && node -e "import('@browserbasehq/stagehand').then(m=>console.log('PA_PROBE_OK Stagehand export:', typeof m.Stagehand))"reproduced$ mktemp -d && npm install @browserbasehq/stagehand && node -e "import('@browserbasehq/stagehand').then(m=>console.log('PA_PROBE_OK Stagehand export:', typeof m.Stagehand))"
\|/-
added 49 packages in 622ms
-PA_PROBE_OK Stagehand export: function
Claims vs evidence — vendor claims reconciled against independent verdictsClaims vs evidence
5 of 12 testable claims verified · 0 contradicted → integrity 42/100
14 distinct capability claims found in Stagehand’s own claimed-docs/GitHub materials, reconciled against our judge’s independent verdicts.
5
Verified
7
Unverified
0
Contradicted
12
Undersold
Verified (8)
“Can execute page actions using natural-language instructions”
Operate the product with natural-language commandsfullproof ↗
“Can execute page actions using natural-language instructions”
Drive the page through DOM-understanding action primitives (act/click/type on described elements) that survive selector and layout changesfullproof ↗
“observe() discovers actionable elements and returns them as previewable actions before executing”
Preview candidate actions on the current page (observe/plan) before committing the agent to actfullproof ↗
“Supports falling back to plain Playwright page methods when you already know the selector”
Connect my existing Playwright, Puppeteer, or CDP automation code to the product's browsers instead of rewriting itpartialproof ↗
“selfHeal option re-infers an action automatically when its recorded selector breaks”
Drive the page through DOM-understanding action primitives (act/click/type on described elements) that survive selector and layout changesfullproof ↗
“Exposes persistent Stagehand browser tools to a Claude Code agent over an MCP/stdio server”
“Automatically traverses iFrames and shadow DOM elements without extra configuration”
Drive the page through DOM-understanding action primitives (act/click/type on described elements) that survive selector and layout changesfullproof ↗
“Can attach to any already-running Chromium browser over CDP by URL”
Connect my existing Playwright, Puppeteer, or CDP automation code to the product's browsers instead of rewriting itpartialproof ↗
Unverified (8)
“extract() pulls structured, schema-shaped data from a page via instruction + output shape”
Extract typed, schema-validated data (Zod/Pydantic-style) from pages the agent visits, not just raw textfullproof ↗
“Caches act/observe/extract results server-side to cut LLM cost and latency on repeat runs”
Cache resolved actions or generated code so repeat runs replay deterministically at lower cost and latency than re-prompting the LLMfullproof ↗
“Persists local browser profile (cookies, local storage) across runs via a user data directory”
Persist logged-in browser state in reusable profiles so agents skip the login wall on every subsequent runfullproof ↗
“Browserbase contexts persist browser session data across cloud runs”
Persist logged-in browser state in reusable profiles so agents skip the login wall on every subsequent runfullproof ↗
“Browserbase sessions can run in one of four regions to reduce latency and meet data-residency needs”
Choose where my data is stored (region/residency)partialproof ↗
“Browserbase dashboard gives real-time browser screen recording and replay of automation sessions”
Debug a failed agent run from recorded replays — video, screenshots, step-by-step action timelinespartialproof ↗
“Browserbase dashboard gives real-time browser screen recording and replay of automation sessions”
Watch a session live and take human control mid-run when the agent gets stuckpartialproof ↗
“Can attach to any already-running Chromium browser over CDP by URL”
Run the agent against a local browser on my own machine for development, without any cloud accountfullproof ↗
Undersold (12)
Point an agent at llms.txt or agent-oriented docsfullproof ↗
Run the product headlessly / in CI for automationfullproof ↗
Drive the product through a documented public APIfullproof ↗
Set up automations that run autonomously in the backgroundpartialproof ↗
Delegate tasks to a built-in AI assistant inside the productfullproof ↗
Plug the browser layer into agent frameworks (Claude Agent SDK, Vercel AI SDK, LangChain, CrewAI) through documented adapterspartialproof ↗
Hand the product a natural-language goal and it completes a multi-step web task end to end — navigating, filling forms, and clicking through flowspartialproof ↗
Compose repeatable multi-step workflows with loops, conditionals, and parameters instead of one-shot promptspartialproof ↗
Rely on a documented captcha stance — automatic solving, human fallback, or explicit non-support — instead of silent task failurespartialproof ↗
Enable stealth fingerprinting and residential or geo-targeted proxies so legitimate automations aren't blocked as botspartialproof ↗
Claims outside our story set (1)
Real capability claims found in Stagehand’s own materials, but no story in this arena’s taxonomy covers them yet — that’s feedback on the taxonomy, not a mark against the product.
“WebMCP lets an agent discover and invoke a site's own tools directly instead of multi-step clicking”
source ↗
Business model
MIT-licensed open-source framework (TypeScript and Python) that runs on any local Chrome for free; pairing it with Browserbase's managed cloud browsers is where vendor usage pricing applies.
pricing ↗Score trend
How this product’s scores have moved as evidence and verdicts are re-derived — a point per change, not per day.
Try Experimental
Run it in the microterminal →Recorded agent sessions — and a live MCP handshake where the vendor ships one.
Flag
⚑ Flag a verdictThink a verdict is wrong? Opens a prefilled GitHub issue — or use the ⚑ next to any verdict above.
For agents
Agent surface uptime llms.txt 100% (30d, checked every 6h since Sep 8 '26)