Rank #1 of 7 in AI Inference Providers
 vs Together AI
 vs Fireworks AI
 vs Cerebras Inference
 vs DeepInfra
 vs Baseten
Showcase
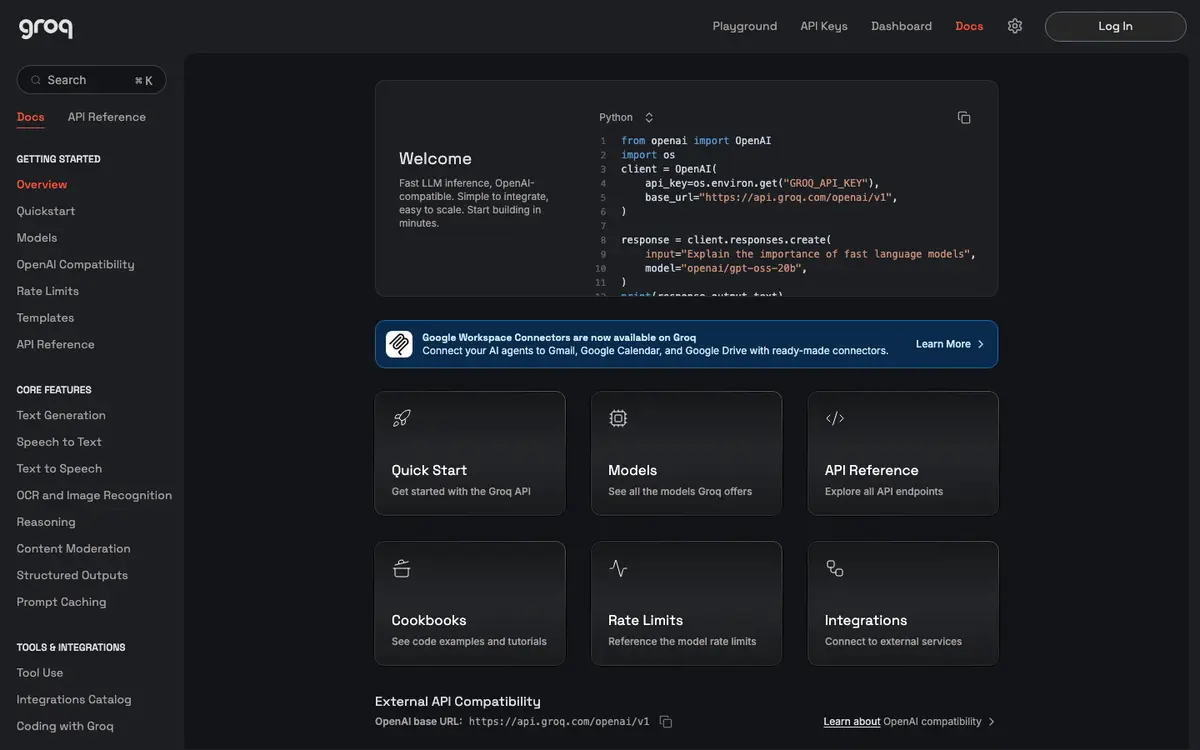
Verified integrations
Connections to other tracked products — hover a chip for the verbatim evidence quote behind it.


By theme — the product's score on each story themeBy theme
Agenticness — how well agents can access and operate the productAgenticnessevidence →
How well agents can access and operate the product
Automation depth — how much of the product can run unattendedAutomation depthevidence →
How much of the product can run unattended
Batch async — stories about batch async in this arenaBatch asyncevidence →
Stories about batch async in this arena
Dedicated capacity — stories about dedicated capacity in this arenaDedicated capacityevidence →
Stories about dedicated capacity in this arena
Fine tune serving — stories about fine tune serving in this arenaFine tune servingevidence →
Stories about fine tune serving in this arena
Model catalog — stories about model catalog in this arenaModel catalogevidence →
Stories about model catalog in this arena
Multimodal — stories about multimodal in this arenaMultimodalevidence →
Stories about multimodal in this arena
Openai compat — stories about openai compat in this arenaOpenai compatevidence →
Stories about openai compat in this arena
Openness — open source, data portability, and self-hosting storiesOpennessevidence →
Open source, data portability, and self-hosting stories
Pricing limits — free-tier ceilings, usage caps, and rate limits before you have to payPricing limitsevidence →
Free-tier ceilings, usage caps, and rate limits before you have to pay
Privacy posture — data-handling and privacy storiesPrivacy postureevidence →
Data-handling and privacy stories
Reliability status — stories about reliability status in this arenaReliability statusevidence →
Stories about reliability status in this arena
Speed latency — stories about speed latency in this arenaSpeed latencyevidence →
Stories about speed latency in this arena
Structured tool calling — stories about structured tool calling in this arenaStructured tool callingevidence →
Stories about structured tool calling in this arena
Story verdicts — every judged story with its evidenceStory verdicts
What’s free: 0 free · 2 paid · 0 enterprise · 23 not stated in evidence
Follow the green: where the map greys out is where Groq stops today. ✓ full · ~ partial · ! disputed · — none · n/a not applicable.
Agenticness — how well agents can access and operate the productAgenticness
How well agents can access and operate the product
API surface
Drive the product through a documented public API
✓9/10
unlocks → Webhooks · Scoped API keys · Machine-readable spec · Versioning policy · API sandbox · Official CLI · Full data export
Subscribe to events via webhooks
—–
Build against official SDKs
✓8/10
Issue scoped/least-privilege API credentials for an agent
—0/10
Connect an agent via an official MCP server
~4/10
Download a machine-readable API spec (OpenAPI or equivalent)
—0/10
Rely on versioned APIs with a documented deprecation policy
—–
Test against a sandbox environment without touching production data
—–
Explore an interactive API reference with runnable examples
~4/10
Docs for agents
Point an agent at llms.txt or agent-oriented docs
✓9/10
Agentic features
Delegate tasks to a built-in AI assistant inside the product
—–
Operate the product with natural-language commands
~6/10
unlocks → Autonomous automations
Plug MCP servers into this product so it can use their tools
✓8/10
Get AI-generated insights and suggestions from my data inside the product
n/an/a
Set up automations that run autonomously in the background
—0/10
Automation depth — how much of the product can run unattendedAutomation depth
How much of the product can run unattended
Batch async — stories about batch async in this arenaBatch async
Stories about batch async in this arena
Dedicated capacity — stories about dedicated capacity in this arenaDedicated capacity
Stories about dedicated capacity in this arena
Fine tune serving — stories about fine tune serving in this arenaFine tune serving
Stories about fine tune serving in this arena
Model catalog — stories about model catalog in this arenaModel catalog
Stories about model catalog in this arena
Catalog
Multimodal — stories about multimodal in this arenaMultimodal
Stories about multimodal in this arena
Openai compat — stories about openai compat in this arenaOpenai compat
Stories about openai compat in this arena
Compat
Openness — open source, data portability, and self-hosting storiesOpenness
Open source, data portability, and self-hosting stories
Pricing limits — free-tier ceilings, usage caps, and rate limits before you have to payPricing limits
Free-tier ceilings, usage caps, and rate limits before you have to pay
Privacy posture — data-handling and privacy storiesPrivacy posture
Data-handling and privacy stories
Reliability status — stories about reliability status in this arenaReliability status
Stories about reliability status in this arena
Speed latency — stories about speed latency in this arenaSpeed latency
Stories about speed latency in this arena
Structured tool calling — stories about structured tool calling in this arenaStructured tool calling
Stories about structured tool calling in this arena
Sorted by importance (agentic first) (high → low) · 53/53 stories · click a row’s chevron for the rationale and evidence
Drive the product through a documented public API G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 3 | full | 9/10 | Tprobed⚿ | |
Plug MCP servers into this product so it can use their tools G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 3 | full | 8/10 | Tprobed | |
Connect an agent via an official MCP server G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 3 | partial | 4/10 | Tprobed | |
Delegate tasks to a built-in AI assistant inside the product G Agentic features | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 3 | none | untested | none yet | |
Point an agent at llms.txt or agent-oriented docs G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | full | 9/10 | Tprobed | |
Build against official SDKs G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | full | 8/10 | Cclaimed | |
Run the product headlessly / in CI for automation G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | full | 8/10 | Tprobed⚿ | |
Operate the product with natural-language commands G Agentic features | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | partial | 6/10 | Cclaimed | |
Explore an interactive API reference with runnable examples G Api quality | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | partial | 4/10 | Tprobed | |
Download a machine-readable API spec (OpenAPI or equivalent) G Api quality | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | none | 0/10 | ||
Issue scoped/least-privilege API credentials for an agent G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | none | 0/10 | ||
Set up automations that run autonomously in the background G Agentic features | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | none | 0/10 | ||
Get AI-generated insights and suggestions from my data inside the product G Agentic features | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | n/a | untested | none yet | |
Rely on versioned APIs with a documented deprecation policy G Api quality | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | none | untested | none yet | |
Subscribe to events via webhooks G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | none | untested | none yet | |
Use an official CLI G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | none | untested | none yet | |
Test against a sandbox environment without touching production data G Api quality | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 1 | none | untested | none yet | |
Point an existing OpenAI SDK client at the provider by changing only the base URL and API key C Compat | developer | Openai compat — stories about openai compat in this arenaOpenai compat | 3 | full | 9/10 | Tprobed⚿ | |
Stream completions token by token over SSE for responsive user experiences C Serving | developer | Speed latency — stories about speed latency in this arenaSpeed latency | 3 | full | 9/10 | Xcommunity | |
Enforce structured outputs against a JSON schema (or grammar) so model responses parse reliably C Structured | developer | Structured tool calling — stories about structured tool calling in this arenaStructured tool calling | 3 | full | 8/10 | Cclaimed | |
Have an agent switch to or away from this provider mid-workflow because it speaks the standard chat-completions API without provider-specific code changes C Compat | ai-native user | Openai compat — stories about openai compat in this arenaOpenai compat | 3 | full | 8/10 | Tprobed⚿ | |
Choose among a broad catalog of current open-weight model families (Llama, Qwen, DeepSeek, GPT-OSS and peers) on shared serverless endpoints C Catalog | developer | Model catalog — stories about model catalog in this arenaModel catalog | 3 | partial | 6/10 | Tprobed⚿ | |
Serve latency-sensitive workloads with fast time-to-first-token and high-throughput generation C Serving | developer | Speed latency — stories about speed latency in this arenaSpeed latency | 3 | disputed | 6/10 | Dcontradicted | |
Rely on faithful function/tool calling — including parallel and multi-step tool use — so agent loops run on open models without breaking C Tools | ai-native user | Structured tool calling — stories about structured tool calling in this arenaStructured tool calling | 3 | partial | 5/10 | Xcommunity | |
See public per-token prices for every hosted model without talking to sales G Pricing | founder | Pricing limits — free-tier ceilings, usage caps, and rate limits before you have to payPricing limits | 3 | disputed | 4/10 | Dcontradicted | |
Self-host the core product G | ai-native user | Openness — open source, data portability, and self-hosting storiesOpenness | 3 | n/a | 0/10 | ||
Define rules that trigger actions automatically on events G | ai-native user | Automation depth — how much of the product can run unattendedAutomation depth | 3 | n/a | untested | none yet | |
Export all of my data in open formats and leave G | ai-native user | Openness — open source, data portability, and self-hosting storiesOpenness | 3 | none | untested | none yet | |
Prevent my data from being used to train AI models G | ai-native user | Privacy posture — data-handling and privacy storiesPrivacy posture | 3 | none | untested | none yet | |
Have an agent enumerate the live model catalog programmatically via a documented GET /v1/models-style endpoint C Catalog | ai-native user | Model catalog — stories about model catalog in this arenaModel catalog | 2 | full | 8/10 | Tprobed⚿ | |
Submit asynchronous batch inference jobs at a documented discount versus real-time pricing G Batch | ml-engineer | Batch async — stories about batch async in this arenaBatch async | 2 | full | 8/10 | Cclaimed | |
Perform bulk operations across many items at once G | ai-native user | Automation depth — how much of the product can run unattendedAutomation depth | 2 | fullpaid | 7/10 | Cclaimed | |
Plug the provider into coding agents and agent frameworks through documented, first-party integration guides C Compat | ai-native user | Openai compat — stories about openai compat in this arenaOpenai compat | 2 | partial | 7/10 | Tprobed | |
Do everything through the API that I can do in the UI G | ai-native user | Openness — open source, data portability, and self-hosting storiesOpenness | 2 | partial | 6/10 | Tprobed | |
Upload and serve my own custom model weights or LoRA adapters C Fine tune | ml-engineer | Fine tune serving — stories about fine tune serving in this arenaFine tune serving | 2 | partial | 6/10 | Cclaimed | |
Check a public status page with incident history before betting production traffic on the platform G Reliability | founder | Reliability status — stories about reliability status in this arenaReliability status | 2 | partial | 5/10 | Tprobed | |
Get newly released open-weight models on the platform quickly after their public release C Catalog | ml-engineer | Model catalog — stories about model catalog in this arenaModel catalog | 2 | partial | 5/10 | Xcommunity | |
Read documented rate limits and how they scale across usage tiers before I hit them in production G Limits | developer | Pricing limits — free-tier ceilings, usage caps, and rate limits before you have to payPricing limits | 2 | partialpaid | 5/10 | Cclaimed | |
See published tokens-per-second or latency numbers, benchmarks, or load-testing guides backing the provider's speed claims C Benchmarks | ml-engineer | Speed latency — stories about speed latency in this arenaSpeed latency | 2 | disputed | 5/10 | Dcontradicted | |
Deploy a model on dedicated GPU capacity with autoscaling so my traffic is isolated from the shared serverless pool C Dedicated | ml-engineer | Dedicated capacity — stories about dedicated capacity in this arenaDedicated capacity | 2 | none | 0/10 | ||
Fine-tune a supported base model on my own data and serve the result on the same platform C Fine tune | ml-engineer | Fine tune serving — stories about fine tune serving in this arenaFine tune serving | 2 | none | 0/10 | ||
Choose where my data is stored (region/residency) G | ai-native user | Privacy posture — data-handling and privacy storiesPrivacy posture | 2 | none | untested | none yet | |
Control data retention and deletion G | ai-native user | Privacy posture — data-handling and privacy storiesPrivacy posture | 2 | none | untested | none yet | |
Opt out of telemetry and usage tracking G | ai-native user | Privacy posture — data-handling and privacy storiesPrivacy posture | 2 | none | untested | none yet | |
Read the product's source under an open license G | ai-native user | Openness — open source, data portability, and self-hosting storiesOpenness | 2 | none | untested | none yet | |
Schedule recurring jobs or workflows G | ai-native user | Automation depth — how much of the product can run unattendedAutomation depth | 2 | n/a | untested | none yet | |
Set spending caps or budget alerts so a runaway workload cannot generate an unbounded bill G Pricing | founder | Pricing limits — free-tier ceilings, usage caps, and rate limits before you have to payPricing limits | 1 | full | 8/10 | Cclaimed | |
Call vision, audio, or image-generation models beyond text chat on the same platform C Modalities | developer | Multimodal — stories about multimodal in this arenaMultimodal | 1 | partial | 6/10 | Cclaimed | |
Get a stated availability SLA on paid or enterprise tiers C Reliability | founder | Reliability status — stories about reliability status in this arenaReliability status | 1 | none | 0/10 | ||
Rely on a documented deprecation policy with advance notice before a hosted model is removed C Catalog | developer | Model catalog — stories about model catalog in this arenaModel catalog | 1 | none | 0/10 | ||
Benefit from prompt/prefix caching that reduces latency or cost on repeated context C Serving | ml-engineer | Speed latency — stories about speed latency in this arenaSpeed latency | 1 | none | untested | none yet | |
Generate embeddings (and rerank results) for retrieval pipelines without a second vendor C Modalities | developer | Multimodal — stories about multimodal in this arenaMultimodal | 1 | none | untested | none yet | |
Version, review, and roll back my automations G | ai-native user | Automation depth — how much of the product can run unattendedAutomation depth | 1 | n/a | untested | none yet |
Opportunities — the stories that would move this product's scores, from its own judged verdictsOpportunitiestop 8 of 32 stories with headroom
What would move Groq’s scores — derived from its own judged verdicts, biggest headroom first. Each line quotes what the judge found missing; shipping it (or evidencing it publicly) is the fix.
Agenticness — how well agents can access and operate the productDelegate tasks to a built-in AI assistant inside the product
nonemoves Built-in AIimpact 45
The axis applies to this product kind (peer products hold positive or none verdicts on this story), so lack of evidence for an applicable capability is "none", never "na".
Openness — open source, data portability, and self-hosting storiesExport all of my data in open formats and leave
nonemoves PA Scoreimpact 30
Groq's docs cover API usage, models, tool-use, batch processing and billing, but nothing addresses exporting account data, conversation history, or batch outputs in open/portable formats, nor any account-closure data dump.
Privacy posture — data-handling and privacy storiesPrevent my data from being used to train AI models
nonemoves PA Scoreimpact 30
No evidence pack item addresses data usage/training policies, opt-out controls, or privacy commitments regarding whether user data is used to train Groq's models.
Agenticness — how well agents can access and operate the productSet up automations that run autonomously in the background
nonemoves Built-in AIimpact 30
Missing: any documented scheduler, cron/trigger mechanism, persistent background agent runtime, or workflow orchestration feature that lets a user 'set up' an automation to run unattended.
Agenticness — how well agents can access and operate the productUse an official CLI
nonemoves agent-readyimpact 30
No evidence of an official Groq CLI tool; documentation covers SDKs (Python/TypeScript), REST API, and MCP integration but no CLI is mentioned anywhere in the evidence pack.
Agenticness — how well agents can access and operate the productIssue scoped/least-privilege API credentials for an agent
nonemoves agent-readyimpact 30
Evidence covers billing spend limits and general API key auth (single api_key parameter) but shows no support for scoped/least-privilege credentials such as role-based keys, granular permission scopes, or per-agent restricted tokens; only one flat API key model is documented.
Agenticness — how well agents can access and operate the productSubscribe to events via webhooks
nonemoves agent-readyimpact 30
No evidence anywhere in the pack of a webhooks/event-subscription feature for Groq's API—only synchronous/streaming inference, batch, tool-use/MCP, and admin/billing docs are covered.
Agenticness — how well agents can access and operate the productDownload a machine-readable API spec (OpenAPI or equivalent)
nonemoves API qualityimpact 30
Groq's API is OpenAI-compatible and well documented, but there is no evidence of a downloadable OpenAPI/Swagger spec; a direct probe of common spec paths (openapi.json, swagger.json, etc.) all returned 404, and no docs page links to a machine-readable spec.
Showing the top 8 of 32 — every none/partial verdict in the story verdicts table is headroom.
Think a verdict is wrong? Every verdicts-table row has a Flag link — see the methodology.
Coverage map — which docs area, API section, or community source covers which judged storiesCoverage map7 surfaces · 28 covered stories
Where the cited evidence behind each covered verdict came from — the same citations the verdicts table shows, no extra judging.
docs27 stories
- Point an agent at llms.txt or agent-oriented docs
- Run the product headlessly / in CI for automation
- Plug MCP servers into this product so it can use their tools
- Connect an agent via an official MCP server
- Drive the product through a documented public API
- Build against official SDKs
- Operate the product with natural-language commands
- Explore an interactive API reference with runnable examples
- Perform bulk operations across many items at once
- Submit asynchronous batch inference jobs at a documented discount versus real-time pricing
- Upload and serve my own custom model weights or LoRA adapters
- Get newly released open-weight models on the platform quickly after their public release
- Have an agent enumerate the live model catalog programmatically via a documented GET /v1/models-style endpoint
- Choose among a broad catalog of current open-weight model families (Llama, Qwen, DeepSeek, GPT-OSS and peers) on shared serverless endpoints
- Call vision, audio, or image-generation models beyond text chat on the same platform
- Plug the provider into coding agents and agent frameworks through documented, first-party integration guides
- Have an agent switch to or away from this provider mid-workflow because it speaks the standard chat-completions API without provider-specific code changes
- Point an existing OpenAI SDK client at the provider by changing only the base URL and API key
- Do everything through the API that I can do in the UI
- Read documented rate limits and how they scale across usage tiers before I hit them in production
- Set spending caps or budget alerts so a runaway workload cannot generate an unbounded bill
- See public per-token prices for every hosted model without talking to sales
- See published tokens-per-second or latency numbers, benchmarks, or load-testing guides backing the provider's speed claims
- Serve latency-sensitive workloads with fast time-to-first-token and high-throughput generation
- Stream completions token by token over SSE for responsive user experiences
- Enforce structured outputs against a JSON schema (or grammar) so model responses parse reliably
- Rely on faithful function/tool calling — including parallel and multi-step tool use — so agent loops run on open models without breaking
Hacker News8 stories
- Get newly released open-weight models on the platform quickly after their public release
- Choose among a broad catalog of current open-weight model families (Llama, Qwen, DeepSeek, GPT-OSS and peers) on shared serverless endpoints
- Plug the provider into coding agents and agent frameworks through documented, first-party integration guides
- See public per-token prices for every hosted model without talking to sales
- See published tokens-per-second or latency numbers, benchmarks, or load-testing guides backing the provider's speed claims
- Serve latency-sensitive workloads with fast time-to-first-token and high-throughput generation
- Stream completions token by token over SSE for responsive user experiences
- Rely on faithful function/tool calling — including parallel and multi-step tool use — so agent loops run on open models without breaking
Openai docs6 stories
- Run the product headlessly / in CI for automation
- Drive the product through a documented public API
- Have an agent enumerate the live model catalog programmatically via a documented GET /v1/models-style endpoint
- Choose among a broad catalog of current open-weight model families (Llama, Qwen, DeepSeek, GPT-OSS and peers) on shared serverless endpoints
- Have an agent switch to or away from this provider mid-workflow because it speaks the standard chat-completions API without provider-specific code changes
- Point an existing OpenAI SDK client at the provider by changing only the base URL and API key
OpenAPI spec3 stories
GitHub README3 stories
groqstatus.com2 stories
Claims vs evidence — vendor claims reconciled against independent verdictsClaims vs evidence
7 of 13 testable claims verified · 0 contradicted → integrity 54/100
18 distinct capability claims found in Groq’s own claimed-docs/GitHub materials, reconciled against our judge’s independent verdicts.
7
Verified
6
Unverified
0
Contradicted
12
Undersold
Verified (10)
“OpenAI-compatible chat completions API for fast LLM inference”
Point an existing OpenAI SDK client at the provider by changing only the base URL and API keyfullproof ↗
“Point existing OpenAI SDK client at Groq by swapping api_key and base_url”
Point an existing OpenAI SDK client at the provider by changing only the base URL and API keyfullproof ↗
“Hosts GPT-OSS 120B open-weight model with built-in browser search, code execution and reasoning”
Choose among a broad catalog of current open-weight model families (Llama, Qwen, DeepSeek, GPT-OSS and peers) on shared serverless endpointspartialproof ↗
“Tool use / function calling lets the model take autonomous actions”
Rely on faithful function/tool calling — including parallel and multi-step tool use — so agent loops run on open models without breakingpartialproof ↗
“Point to an MCP server URL and Groq automatically uses its tools without custom tool logic”
Plug MCP servers into this product so it can use their toolsfullproof ↗
“Streaming completions token-by-token by setting stream=True”
Stream completions token by token over SSE for responsive user experiencesfullproof ↗
“Chat Completions API enables conversational interactions with hosted LLMs”
Drive the product through a documented public APIfullproof ↗
“Responses API is fully compatible with OpenAI's Responses API for easy integration”
Have an agent switch to or away from this provider mid-workflow because it speaks the standard chat-completions API without provider-specific code changesfullproof ↗
“Tool definitions passed as JSON schema via the tools parameter to enable function calling”
Rely on faithful function/tool calling — including parallel and multi-step tool use — so agent loops run on open models without breakingpartialproof ↗
“MCP tool use via Responses API over HTTPS with Groq handling all orchestration”
Plug MCP servers into this product so it can use their toolsfullproof ↗
Unverified (8)
“Structured outputs with strict:true guarantee output matches a JSON schema exactly”
Enforce structured outputs against a JSON schema (or grammar) so model responses parse reliablyfullproof ↗
“Batch processing runs thousands of async API requests at 50% lower cost with a 24hr-7day window”
Submit asynchronous batch inference jobs at a documented discount versus real-time pricingfullproof ↗
“Multiple service tiers (auto/on-demand/flex) let you tune for latency, throughput and reliability via service_tier parameter”
Read documented rate limits and how they scale across usage tiers before I hit them in productionpartialproof ↗
“Flex processing tier gives paid customers 10x higher rate limits than on-demand at the same price”
Read documented rate limits and how they scale across usage tiers before I hit them in productionpartialproof ↗
“Upload and run inference with your own pre-made LoRA adapters on Groq's infrastructure”
Upload and serve my own custom model weights or LoRA adapterspartialproof ↗
“Set automated spend limits and receive budget alerts”
Set spending caps or budget alerts so a runaway workload cannot generate an unbounded billfullproof ↗
“Responses API supports text and image inputs, stateful conversations, and function calling”
Call vision, audio, or image-generation models beyond text chat on the same platformpartialproof ↗
“Audio transcription endpoint (e.g. whisper-large-v3-turbo) accepts file uploads”
Call vision, audio, or image-generation models beyond text chat on the same platformpartialproof ↗
Undersold (12)
Point an agent at llms.txt or agent-oriented docsfullproof ↗
Run the product headlessly / in CI for automationfullproof ↗
Operate the product with natural-language commandspartialproof ↗
Explore an interactive API reference with runnable examplespartialproof ↗
Perform bulk operations across many items at oncefullproof ↗
Get newly released open-weight models on the platform quickly after their public releasepartialproof ↗
Have an agent enumerate the live model catalog programmatically via a documented GET /v1/models-style endpointfullproof ↗
Plug the provider into coding agents and agent frameworks through documented, first-party integration guidespartialproof ↗
Do everything through the API that I can do in the UIpartialproof ↗
Check a public status page with incident history before betting production traffic on the platformpartialproof ↗
Pricing signals
Checked 2026-09-07. We never estimate a price we didn’t extract.
Business model
Free tier for evaluation, then pay-as-you-go per-token pricing that varies by model, with Flex/Performance service tiers and enterprise/dedicated capacity priced via sales.
pricing ↗Score trend
How this product’s scores have moved as evidence and verdicts are re-derived — a point per change, not per day.
Flag
⚑ Flag a verdictThink a verdict is wrong? Opens a prefilled GitHub issue — or use the ⚑ next to any verdict above.
For agents
Agent surface uptime llms.txt 100% (30d, checked every 6h since Sep 8 '26)