Rank #3 of 5 in Serverless & Developer Databases

Install
 vs Neon
 vs PlanetScale
 vs ClickHouse
 vs CockroachDB
Showcase
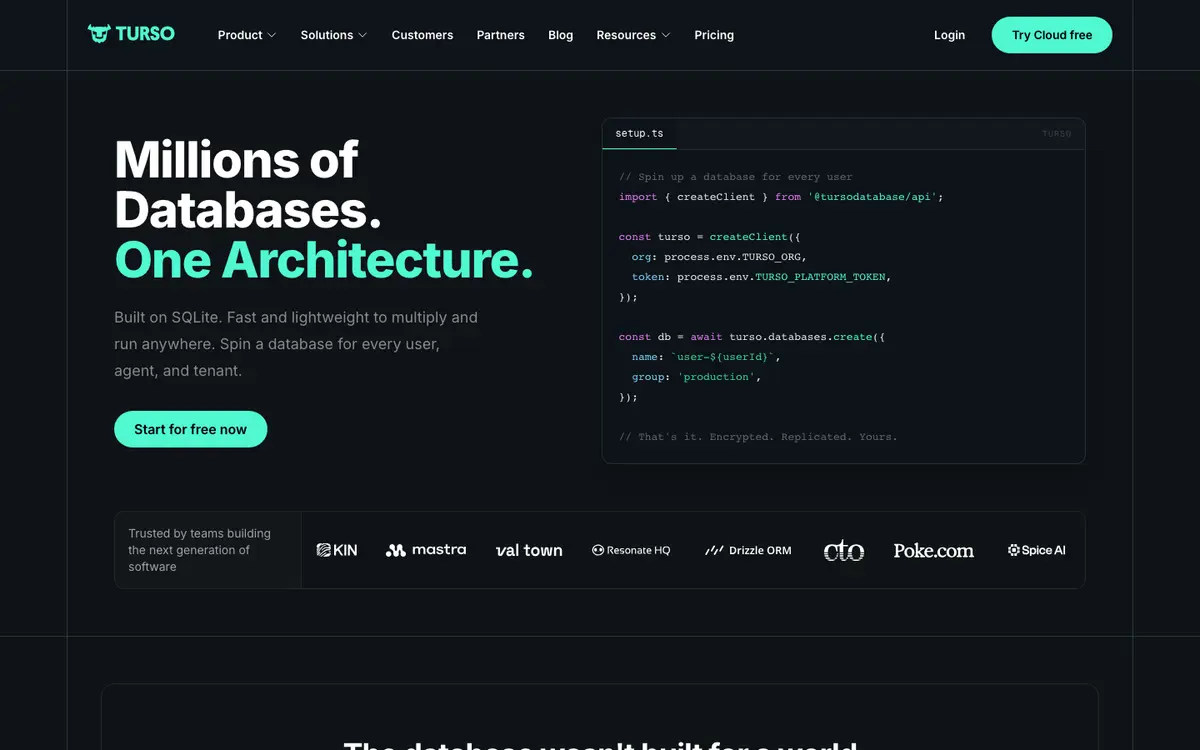
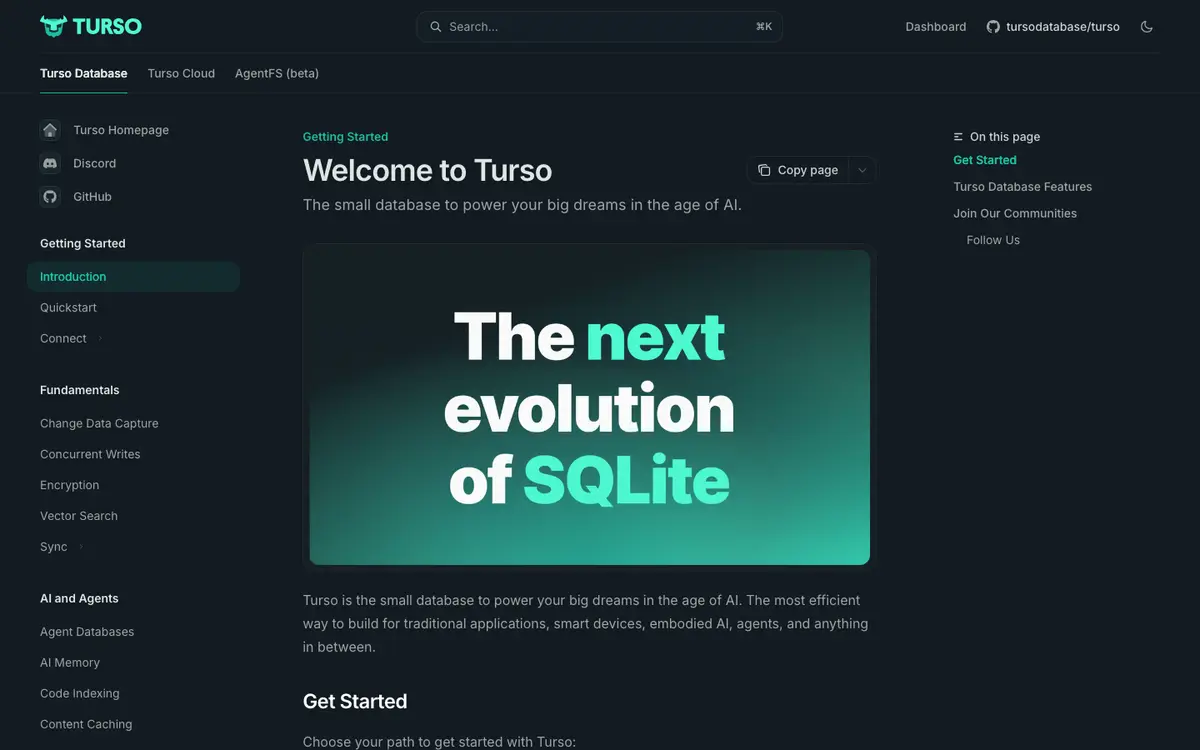
Try itExperimental
See what an agent can do with Turso before you ever sign up. Pick a story: recorded sessions replay real probe-harness transcripts; sandboxed self-drive sessions are designed and gated (docs/TRY-IT.md).
$turso --version # installed via `curl -sSfL https://get.tur.so/install.sh | bash`recorded session — replayed, not liveVerified integrations
No integration evidence found in our corpus for this product yet — that means none was found, never that it doesn’t integrate.
By theme — the product's score on each story themeBy theme
Agent workflows — stories about agent workflows in this arenaAgent workflowsevidence →
Stories about agent workflows in this arena
Agenticness — how well agents can access and operate the productAgenticnessevidence →
How well agents can access and operate the product
Automation depth — how much of the product can run unattendedAutomation depthevidence →
How much of the product can run unattended
Branching workflows — stories about branching workflows in this arenaBranching workflowsevidence →
Stories about branching workflows in this arena
Connectivity pooling — stories about connectivity pooling in this arenaConnectivity poolingevidence →
Stories about connectivity pooling in this arena
Data capabilities — stories about data capabilities in this arenaData capabilitiesevidence →
Stories about data capabilities in this arena
Local dev — stories about local dev in this arenaLocal devevidence →
Stories about local dev in this arena
Migrations schema — stories about migrations schema in this arenaMigrations schemaevidence →
Stories about migrations schema in this arena
Openness — open source, data portability, and self-hosting storiesOpennessevidence →
Open source, data portability, and self-hosting stories
Operations insights — stories about operations insights in this arenaOperations insightsevidence →
Stories about operations insights in this arena
Pricing plans — plan structure and value — what each tier costs and what it unlocksPricing plansevidence →
Plan structure and value — what each tier costs and what it unlocks
Privacy posture — data-handling and privacy storiesPrivacy postureevidence →
Data-handling and privacy stories
Reliability recovery — stories about reliability recovery in this arenaReliability recoveryevidence →
Stories about reliability recovery in this arena
Serverless scale — stories about serverless scale in this arenaServerless scaleevidence →
Stories about serverless scale in this arena
Story verdicts — every judged story with its evidenceStory verdicts
What’s free: 4 free · 1 paid · 0 enterprise · 28 not stated in evidence
Follow the green: where the map greys out is where Turso stops today. ✓ full · ~ partial · ! disputed · — none · n/a not applicable.
Agent workflows — stories about agent workflows in this arenaAgent workflows
Stories about agent workflows in this arena
Agent ops
Agenticness — how well agents can access and operate the productAgenticness
How well agents can access and operate the product
API surface
Drive the product through a documented public API
✓8/10
unlocks → Webhooks · Machine-readable spec · Versioning policy · Full data export · An agent can run SQL and schema operations through scoped tools that distinguish read-only from destructive actions, so I can safely delegate database work
Subscribe to events via webhooks
—–
Build against official SDKs
✓9/10
Issue scoped/least-privilege API credentials for an agent
✓8/10
Connect an agent via an official MCP server
✓8/10
Download a machine-readable API spec (OpenAPI or equivalent)
—0/10
Rely on versioned APIs with a documented deprecation policy
—0/10
Test against a sandbox environment without touching production data
✓8/10
Explore an interactive API reference with runnable examples
—0/10
Agentic features
Delegate tasks to a built-in AI assistant inside the product
—–
Operate the product with natural-language commands
✓8/10
Plug MCP servers into this product so it can use their tools
n/an/a
Get AI-generated insights and suggestions from my data inside the product
—–
Set up automations that run autonomously in the background
~5/10
Automation depth — how much of the product can run unattendedAutomation depth
How much of the product can run unattended
Branching workflows — stories about branching workflows in this arenaBranching workflows
Stories about branching workflows in this arena
Connectivity pooling — stories about connectivity pooling in this arenaConnectivity pooling
Stories about connectivity pooling in this arena
Query over HTTP or WebSockets from serverless and edge functions with an official driver built for short-lived connections
~7/10
Place data or replicas in regions close to my users to keep read latency low worldwide
~6/10
A built-in connection pooler handles thousands of concurrent connections without me operating my own pgbouncer or proxy
—–
Data capabilities — stories about data capabilities in this arenaData capabilities
Stories about data capabilities in this arena
Store embeddings and run vector similarity search natively without adding a separate vector database
✓8/10
Run heavy analytical aggregations over large tables fast enough for dashboards without exporting to a separate warehouse
—0/10
I get real engine compatibility — the Postgres, MySQL, or SQLite dialect and extensions my existing code expects — not a lookalike subset
!4/10
Local dev — stories about local dev in this arenaLocal dev
Stories about local dev in this arena
Migrations schema — stories about migrations schema in this arenaMigrations schema
Stories about migrations schema in this arena
Openness — open source, data portability, and self-hosting storiesOpenness
Open source, data portability, and self-hosting stories
Operations insights — stories about operations insights in this arenaOperations insights
Stories about operations insights in this arena
Pricing plans — plan structure and value — what each tier costs and what it unlocksPricing plans
Plan structure and value — what each tier costs and what it unlocks
Privacy posture — data-handling and privacy storiesPrivacy posture
Data-handling and privacy stories
Reliability recovery — stories about reliability recovery in this arenaReliability recovery
Stories about reliability recovery in this arena
Serverless scale — stories about serverless scale in this arenaServerless scale
Stories about serverless scale in this arena
Sorted by importance (agentic first) (high → low) · 56/56 stories · click a row’s chevron for the rationale and evidence
Connect an agent via an official MCP server G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 3 | full | 8/10 | Tprobed⚿ | |
Drive the product through a documented public API G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 3 | full | 8/10 | Tprobed⚿ | |
Delegate tasks to a built-in AI assistant inside the product G Agentic features | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 3 | none | untested | none yet | |
Plug MCP servers into this product so it can use their tools G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 3 | n/a | untested | none yet | |
Build against official SDKs G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | full | 9/10 | Tprobed⚿ | |
Point an agent at llms.txt or agent-oriented docs G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | full | 9/10 | Tprobed | |
Use an official CLI G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | full | 9/10 | Tprobed | |
Issue scoped/least-privilege API credentials for an agent G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | full | 8/10 | Tprobed⚿ | |
Operate the product with natural-language commands G Agentic features | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | full | 8/10 | Tprobed⚿ | |
Run the product headlessly / in CI for automation G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | full | 8/10 | Tprobed | |
Set up automations that run autonomously in the background G Agentic features | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | partial | 5/10 | Tprobed⚿ | |
Download a machine-readable API spec (OpenAPI or equivalent) G Api quality | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | none | 0/10 | ||
Explore an interactive API reference with runnable examples G Api quality | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | none | 0/10 | ||
Rely on versioned APIs with a documented deprecation policy G Api quality | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | none | 0/10 | ||
Get AI-generated insights and suggestions from my data inside the product G Agentic features | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | none | untested | none yet | |
Subscribe to events via webhooks G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | none | untested | none yet | |
Test against a sandbox environment without touching production data G Api quality | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 1 | full | 8/10 | Tprobed | |
Create a ready-to-connect database in seconds through the CLI or API without capacity planning C Provisioning | developer | Serverless scale — stories about serverless scale in this arenaServerless scale | 3 | full | 9/10 | Tprobed | |
Create an instant copy-on-write branch of my database — schema and data — to develop and test against production-shaped data C Branching | developer | Branching workflows — stories about branching workflows in this arenaBranching workflows | 3 | full | 9/10 | Cclaimed | |
Run the same engine locally and keylessly — no account or cloud dependency — for offline development and CI tests G Local loop | developer | Local dev — stories about local dev in this arenaLocal dev | 3 | fullfree | 9/10 | Tprobed | |
My coding agent can provision a database end to end — create it, fetch the connection string, apply schema, and run queries — through the API, CLI, or MCP without touching the dashboard C Agent ops | ai-native user | Agent workflows — stories about agent workflows in this arenaAgent workflows | 3 | full | 8/10 | Tprobed⚿ | |
Restore or branch the database to any point in time within the retention window to recover from bad writes C Recovery | platform-engineer | Reliability recovery — stories about reliability recovery in this arenaReliability recovery | 3 | full | 8/10 | Cclaimed | |
Self-host the core product G | ai-native user | Openness — open source, data portability, and self-hosting storiesOpenness | 3 | partialfree | 7/10 | Tprobed | |
Ship schema changes safely — online DDL, deploy requests, or branch-and-merge workflows — without locking or breaking production C Migrations | developer | Migrations schema — stories about migrations schema in this arenaMigrations schema | 3 | disputed | 5/10 | Dcontradicted | |
Export all of my data in open formats and leave G | ai-native user | Openness — open source, data portability, and self-hosting storiesOpenness | 3 | disputed | 4/10 | Dcontradicted | |
I get real engine compatibility — the Postgres, MySQL, or SQLite dialect and extensions my existing code expects — not a lookalike subset C Compatibility | developer | Data capabilities — stories about data capabilities in this arenaData capabilities | 3 | disputed | 4/10 | Dcontradicted | |
Define rules that trigger actions automatically on events G | ai-native user | Automation depth — how much of the product can run unattendedAutomation depth | 3 | none | 0/10 | ||
Published per-unit pricing for compute, storage, and traffic lets me predict my bill before committing G Pricing | founder | Pricing plans — plan structure and value — what each tier costs and what it unlocksPricing plans | 3 | none | 0/10 | ||
Idle databases scale to zero so prototypes and side projects cost nothing while the data stays durable C Elasticity | founder | Serverless scale — stories about serverless scale in this arenaServerless scale | 3 | none | untested | none yet | |
Prevent my data from being used to train AI models G | ai-native user | Privacy posture — data-handling and privacy storiesPrivacy posture | 3 | none | untested | none yet | |
Store embeddings and run vector similarity search natively without adding a separate vector database C Ai data | developer | Data capabilities — stories about data capabilities in this arenaData capabilities | 2 | full | 8/10 | Xcommunity | |
The official CLI covers my daily loop — create, connect, shell into, and inspect databases — without opening the dashboard C Local loop | developer | Local dev — stories about local dev in this arenaLocal dev | 2 | full | 8/10 | Tprobed | |
A genuinely usable free tier lets me run real prototypes before paying G Pricing | founder | Pricing plans — plan structure and value — what each tier costs and what it unlocksPricing plans | 2 | fullfree | 7/10 | Xcommunity | |
Cheaply create thousands of isolated databases — one per agent, tenant, or preview — and manage the fleet programmatically C Agent ops | ai-native user | Agent workflows — stories about agent workflows in this arenaAgent workflows | 2 | full | 7/10 | Tprobed | |
Create and tear down per-pull-request database branches automatically from CI or my deploy platform C Branching | platform-engineer | Branching workflows — stories about branching workflows in this arenaBranching workflows | 2 | partial | 7/10 | Tprobed | |
Perform bulk operations across many items at once G | ai-native user | Automation depth — how much of the product can run unattendedAutomation depth | 2 | full | 7/10 | Cclaimed | |
Query over HTTP or WebSockets from serverless and edge functions with an official driver built for short-lived connections C Drivers | developer | Connectivity pooling — stories about connectivity pooling in this arenaConnectivity pooling | 2 | partial | 7/10 | Tprobed | |
Choose where my data is stored (region/residency) G | ai-native user | Privacy posture — data-handling and privacy storiesPrivacy posture | 2 | partialpaid | 6/10 | Cclaimed | |
Control data retention and deletion G | ai-native user | Privacy posture — data-handling and privacy storiesPrivacy posture | 2 | partial | 6/10 | Cclaimed | |
Do everything through the API that I can do in the UI G | ai-native user | Openness — open source, data portability, and self-hosting storiesOpenness | 2 | partial | 6/10 | Tprobed⚿ | |
Place data or replicas in regions close to my users to keep read latency low worldwide C Latency | developer | Connectivity pooling — stories about connectivity pooling in this arenaConnectivity pooling | 2 | partial | 6/10 | Xcommunity | |
Add read replicas and rely on documented high-availability and failover behavior C Availability | platform-engineer | Reliability recovery — stories about reliability recovery in this arenaReliability recovery | 2 | partial | 5/10 | Cclaimed | |
Read the product's source under an open license G | ai-native user | Openness — open source, data portability, and self-hosting storiesOpenness | 2 | partialfree | 5/10 | Tprobed | |
Automatic backups run on a schedule I can see and configure, and restores are self-serve C Recovery | founder | Reliability recovery — stories about reliability recovery in this arenaReliability recovery | 2 | partial | 4/10 | Cclaimed | |
An agent can run SQL and schema operations through scoped tools that distinguish read-only from destructive actions, so I can safely delegate database work C Agent ops | ai-native user | Agent workflows — stories about agent workflows in this arenaAgent workflows | 2 | none | 0/10 | ⚿ | |
Compute autoscales up and down with load automatically, without manual resizes or downtime C Elasticity | platform-engineer | Serverless scale — stories about serverless scale in this arenaServerless scale | 2 | none | 0/10 | ||
Run heavy analytical aggregations over large tables fast enough for dashboards without exporting to a separate warehouse C Analytics | developer | Data capabilities — stories about data capabilities in this arenaData capabilities | 2 | none | 0/10 | ||
A built-in connection pooler handles thousands of concurrent connections without me operating my own pgbouncer or proxy C Pooling | platform-engineer | Connectivity pooling — stories about connectivity pooling in this arenaConnectivity pooling | 2 | none | untested | none yet | |
Opt out of telemetry and usage tracking G | ai-native user | Privacy posture — data-handling and privacy storiesPrivacy posture | 2 | none | untested | none yet | |
Schedule recurring jobs or workflows G | ai-native user | Automation depth — how much of the product can run unattendedAutomation depth | 2 | none | untested | none yet | |
See slow queries, index recommendations, and performance metrics in a built-in insights view C Insights | platform-engineer | Operations insights — stories about operations insights in this arenaOperations insights | 2 | none | untested | none yet | |
The database works out of the box with my ORM and framework (Prisma, Drizzle, Django, Rails) with documented guides C Integrations | developer | Migrations schema — stories about migrations schema in this arenaMigrations schema | 2 | none | untested | none yet | |
Reset a branch from its parent or restore it to an earlier state without rebuilding from a dump C Branching | developer | Branching workflows — stories about branching workflows in this arenaBranching workflows | 1 | partial | 6/10 | Cclaimed | |
Version, review, and roll back my automations G | ai-native user | Automation depth — how much of the product can run unattendedAutomation depth | 1 | partial | 5/10 | Tprobed⚿ | |
Import an existing production database with minimal downtime using a documented migration path C Migrations | developer | Migrations schema — stories about migrations schema in this arenaMigrations schema | 1 | partial | 4/10 | Cclaimed | |
Set spend caps or usage alerts so a runaway query or traffic spike cannot produce a surprise bill G Cost controls | founder | Operations insights — stories about operations insights in this arenaOperations insights | 1 | none | 0/10 |
Opportunities — the stories that would move this product's scores, from its own judged verdictsOpportunitiestop 8 of 33 stories with headroom
What would move Turso’s scores — derived from its own judged verdicts, biggest headroom first. Each line quotes what the judge found missing; shipping it (or evidencing it publicly) is the fix.
Agenticness — how well agents can access and operate the productDelegate tasks to a built-in AI assistant inside the product
nonemoves Built-in AIimpact 45
Turso's evidence only shows an MCP server letting external AI agents connect to and manage Turso (agent-as-client), not a built-in AI assistant embedded within the Turso product itself that users could delegate tasks to.
Automation depth — how much of the product can run unattendedDefine rules that trigger actions automatically on events
nonemoves PA Scoreimpact 30
The evidence pack contains no mention of SQL triggers, webhooks, change-data-capture, or any event-driven rule/action mechanism built into Turso.
Privacy posture — data-handling and privacy storiesPrevent my data from being used to train AI models
nonemoves PA Scoreimpact 30
The evidence pack contains no policy statement, terms-of-service excerpt, or documentation addressing whether Turso uses customer database content to train AI models — despite Turso being a data-storage platform with AI-agent integrations (MCP) where such a privacy assurance would be a reasonable buyer question.
Serverless scale — stories about serverless scale in this arenaIdle databases scale to zero so prototypes and side projects cost nothing while the data stays durable
nonemoves PA Scoreimpact 30
The evidence pack covers durability, branching, embedded replicas, vector search, and pricing tiers, but nowhere states that idle Turso databases scale to zero or that idle usage incurs no cost while data remains durable.
Pricing plans — plan structure and value — what each tier costs and what it unlocksPublished per-unit pricing for compute, storage, and traffic lets me predict my bill before committing
nonemoves PA Scoreimpact 30
The evidence only shows a pricing page exists with tier names and feature toggles (e.g., 'AWS VPC Allow Lists', 'Free', 'Developer') but no per-unit rates for compute, storage, or traffic (e.g., $/GB, $/row-read, $/egress) are cited anywhere in the pack, so a founder cannot predict a bill from this evidence.
Agenticness — how well agents can access and operate the productGet AI-generated insights and suggestions from my data inside the product
nonemoves Built-in AIimpact 30
Turso provides infrastructure primitives (native vector search, MCP integration for agents to run SQL) but no evidence of a built-in feature that itself generates AI insights or suggestions about the user's stored data — it merely provides raw building blocks for others to build such features on top.
Agenticness — how well agents can access and operate the productSubscribe to events via webhooks
nonemoves agent-readyimpact 30
No evidence anywhere in the pack of webhook support or event subscription mechanisms; Turso's documented integration surface is CLI, SDKs, API, and MCP, not webhooks.
Agenticness — how well agents can access and operate the productExplore an interactive API reference with runnable examples
nonemoves API qualityimpact 30
Turso has API reference docs (turso-docs-8) but no evidence of an interactive, runnable-example reference; a direct probe for OpenAPI/Swagger interactive docs returned 404 on all candidate paths, indicating no such interactive reference is exposed.
Showing the top 8 of 33 — every none/partial verdict in the story verdicts table is headroom.
Think a verdict is wrong? Every verdicts-table row has a Flag link — see the methodology.
Coverage map — which docs area, API section, or community source covers which judged storiesCoverage map15 surfaces · 36 covered stories
Where the cited evidence behind each covered verdict came from — the same citations the verdicts table shows, no extra judging.
Local development docs16 stories
- My coding agent can provision a database end to end — create it, fetch the connection string, apply schema, and run queries — through the API, CLI, or MCP without touching the dashboard
- Run the product headlessly / in CI for automation
- Use an official CLI
- Drive the product through a documented public API
- Build against official SDKs
- Test against a sandbox environment without touching production data
- Reset a branch from its parent or restore it to an earlier state without rebuilding from a dump
- Query over HTTP or WebSockets from serverless and edge functions with an official driver built for short-lived connections
- I get real engine compatibility — the Postgres, MySQL, or SQLite dialect and extensions my existing code expects — not a lookalike subset
- The official CLI covers my daily loop — create, connect, shell into, and inspect databases — without opening the dashboard
- Run the same engine locally and keylessly — no account or cloud dependency — for offline development and CI tests
- Import an existing production database with minimal downtime using a documented migration path
- Export all of my data in open formats and leave
- Self-host the core product
- Control data retention and deletion
- Create a ready-to-connect database in seconds through the CLI or API without capacity planning
Features docs16 stories
- Cheaply create thousands of isolated databases — one per agent, tenant, or preview — and manage the fleet programmatically
- Run the product headlessly / in CI for automation
- Set up automations that run autonomously in the background
- Test against a sandbox environment without touching production data
- Version, review, and roll back my automations
- Reset a branch from its parent or restore it to an earlier state without rebuilding from a dump
- Create and tear down per-pull-request database branches automatically from CI or my deploy platform
- Create an instant copy-on-write branch of my database — schema and data — to develop and test against production-shaped data
- Place data or replicas in regions close to my users to keep read latency low worldwide
- Import an existing production database with minimal downtime using a documented migration path
- Ship schema changes safely — online DDL, deploy requests, or branch-and-merge workflows — without locking or breaking production
- Do everything through the API that I can do in the UI
- Control data retention and deletion
- Add read replicas and rely on documented high-availability and failover behavior
- Automatic backups run on a schedule I can see and configure, and restores are self-serve
- Restore or branch the database to any point in time within the retention window to recover from bad writes
API reference11 stories
- My coding agent can provision a database end to end — create it, fetch the connection string, apply schema, and run queries — through the API, CLI, or MCP without touching the dashboard
- Cheaply create thousands of isolated databases — one per agent, tenant, or preview — and manage the fleet programmatically
- Drive the product through a documented public API
- Issue scoped/least-privilege API credentials for an agent
- Build against official SDKs
- Set up automations that run autonomously in the background
- Perform bulk operations across many items at once
- Create and tear down per-pull-request database branches automatically from CI or my deploy platform
- Do everything through the API that I can do in the UI
- Control data retention and deletion
- Create a ready-to-connect database in seconds through the CLI or API without capacity planning
turso.tech11 stories
- Cheaply create thousands of isolated databases — one per agent, tenant, or preview — and manage the fleet programmatically
- Drive the product through a documented public API
- Build against official SDKs
- Perform bulk operations across many items at once
- Create and tear down per-pull-request database branches automatically from CI or my deploy platform
- Query over HTTP or WebSockets from serverless and edge functions with an official driver built for short-lived connections
- I get real engine compatibility — the Postgres, MySQL, or SQLite dialect and extensions my existing code expects — not a lookalike subset
- Export all of my data in open formats and leave
- Choose where my data is stored (region/residency)
- Control data retention and deletion
- Create a ready-to-connect database in seconds through the CLI or API without capacity planning
CLI docs10 stories
- My coding agent can provision a database end to end — create it, fetch the connection string, apply schema, and run queries — through the API, CLI, or MCP without touching the dashboard
- Cheaply create thousands of isolated databases — one per agent, tenant, or preview — and manage the fleet programmatically
- Run the product headlessly / in CI for automation
- Use an official CLI
- Create and tear down per-pull-request database branches automatically from CI or my deploy platform
- The official CLI covers my daily loop — create, connect, shell into, and inspect databases — without opening the dashboard
- Run the same engine locally and keylessly — no account or cloud dependency — for offline development and CI tests
- Read the product's source under an open license
- Self-host the core product
- Create a ready-to-connect database in seconds through the CLI or API without capacity planning
Integrations docs10 stories
- My coding agent can provision a database end to end — create it, fetch the connection string, apply schema, and run queries — through the API, CLI, or MCP without touching the dashboard
- Connect an agent via an official MCP server
- Use an official CLI
- Drive the product through a documented public API
- Issue scoped/least-privilege API credentials for an agent
- Build against official SDKs
- Set up automations that run autonomously in the background
- Operate the product with natural-language commands
- Version, review, and roll back my automations
- Do everything through the API that I can do in the UI
Hacker News8 stories
- Place data or replicas in regions close to my users to keep read latency low worldwide
- Store embeddings and run vector similarity search natively without adding a separate vector database
- I get real engine compatibility — the Postgres, MySQL, or SQLite dialect and extensions my existing code expects — not a lookalike subset
- Ship schema changes safely — online DDL, deploy requests, or branch-and-merge workflows — without locking or breaking production
- Export all of my data in open formats and leave
- Read the product's source under an open license
- Self-host the core product
- A genuinely usable free tier lets me run real prototypes before paying
Quickstart docs6 stories
- My coding agent can provision a database end to end — create it, fetch the connection string, apply schema, and run queries — through the API, CLI, or MCP without touching the dashboard
- Run the product headlessly / in CI for automation
- Use an official CLI
- The official CLI covers my daily loop — create, connect, shell into, and inspect databases — without opening the dashboard
- Do everything through the API that I can do in the UI
- Create a ready-to-connect database in seconds through the CLI or API without capacity planning
Introduction docs5 stories
- Point an agent at llms.txt or agent-oriented docs
- Query over HTTP or WebSockets from serverless and edge functions with an official driver built for short-lived connections
- I get real engine compatibility — the Postgres, MySQL, or SQLite dialect and extensions my existing code expects — not a lookalike subset
- Ship schema changes safely — online DDL, deploy requests, or branch-and-merge workflows — without locking or breaking production
- Export all of my data in open formats and leave
Cloud docs5 stories
- A genuinely usable free tier lets me run real prototypes before paying
- Choose where my data is stored (region/residency)
- Control data retention and deletion
- Add read replicas and rely on documented high-availability and failover behavior
- Automatic backups run on a schedule I can see and configure, and restores are self-serve
SDK docs3 stories
OpenAPI spec2 stories
Pricing docs2 stories
Probe proofs — replayable recordings from the probe harnessProbe proofs
Replayable recordings from our probe harness — see the Prove-It protocol to submit one.
$turso --version # installed via `curl -sSfL https://get.tur.so/install.sh | bash`reproduced$ turso --version # installed via `curl -sSfL https://get.tur.so/install.sh | bash` turso version v1.0.32
$turso dev --db-file /tmp/pa-turso-probe.db --port 8085 # local libSQL, no account — then CREATE/INSERT/SELECT (6*7) over the Hrana HTTP APIreproduced$ turso dev --db-file /tmp/pa-turso-probe.db --port 8085 # local libSQL, no account — then CREATE/INSERT/SELECT (6*7) over the Hrana HTTP API
{"baton":null,"base_url":null,"results":[{"type":"ok","response":{"type":"execute","result":{"cols":[],"rows":[],"affected_row_count":0,"last_insert_rowid":null,"replication_index":"1","rows_read":1,"rows_written":2,"query_duration_ms":0.726}}},{"type":"ok","response":{"type":"execute","result":{"cols":[],"rows":[],"affected_row_count":1,"last_insert_rowid":"6","replication_index":"2","rows_read":1,"rows_written":1,"query_duration_ms":0.084}}},{"type":"ok","response":{"type":"execute","result":{"cols":[{"name":"answer","decltype":null}],"rows":[[{"type":"integer","value":"42"}]],"affected_row_count":0,"last_insert_rowid":null,"replication_index":"2","rows_read":1,"rows_written":0,"query_duration_ms":0.021}}},{"type":"ok","response":{"type":"close"}}]}
sqld listening on port 8085.
$curl -si -X POST https://mcp.turso.ai/mcp -H 'Content-Type: application/json' -d '<jsonrpc initialize>'reproduced$ curl -si -X POST https://mcp.turso.ai/mcp -H 'Content-Type: application/json' -d '<jsonrpc initialize>'
HTTP/2 401
content-type: application/json; charset=utf-8
content-length: 56
date: Sun, 06 Sep 2026 21:11:08 GMT
www-authenticate: Bearer resource_metadata="https://mcp.turso.ai/.well-known/oauth-protected-resource/mcp"
x-cache: Error from cloudfront
via: 1.1 c3b772e11b688f5aa587bd31e7e8e2e8.cloudfront.net (CloudFront)
x-amz-cf-pop: SFO5-P3
alt-svc: h3=":443"; ma=86400
x-amz-cf-id: KdzkjfSHLvVMErC-elt6A7TxPO0PBdx0Nk-xs3qCfDv5eWhHlpEcow==
{"error":"[redacted] contains an invalid number of segments"}
Claims vs evidence — vendor claims reconciled against independent verdictsClaims vs evidence
10 of 17 testable claims verified · 2 contradicted → integrity 35/100
23 distinct capability claims found in Turso’s own claimed-docs/GitHub materials, reconciled against our judge’s independent verdicts.
10
Verified
5
Unverified
2
Contradicted
18
Undersold
Verified (11)
“Create a Turso Cloud database quickly through the quickstart guide”
Create a ready-to-connect database in seconds through the CLI or API without capacity planningfullproof ↗
“Run a local database as a single file with no server process required”
Run the same engine locally and keylessly — no account or cloud dependency — for offline development and CI testsfullproof ↗
“Embedded Replicas serve reads from a local file in microseconds while writes sync to a cloud primary”
Place data or replicas in regions close to my users to keep read latency low worldwidepartialproof ↗
“Native vector search built into the database; store embeddings alongside relational data with no extensions”
Store embeddings and run vector similarity search natively without adding a separate vector databasefullproof ↗
“Provision a dedicated, isolated SQLite database per user or AI agent, created/token-scoped/torn down via API”
Cheaply create thousands of isolated databases — one per agent, tenant, or preview — and manage the fleet programmaticallyfullproof ↗
“MCP-capable agents can manage the Turso Cloud account (orgs, databases, groups) and run SQL without copying an API token”
“Automate branch creation to spin up a new database per pull request from CI”
Create and tear down per-pull-request database branches automatically from CI or my deploy platformpartialproof ↗
“Spin up thousands or millions of isolated databases programmatically as a core architectural feature”
Cheaply create thousands of isolated databases — one per agent, tenant, or preview — and manage the fleet programmaticallyfullproof ↗
“Official SDKs available for TypeScript, Python, Rust, and Go”
“CLI command creates a new database directly (turso db create)”
“Connect to a database via the CLI's shell command”
The official CLI covers my daily loop — create, connect, shell into, and inspect databases — without opening the dashboardfullproof ↗
Unverified (7)
“Create a copy-on-write branch for development/testing without touching the original database”
Create an instant copy-on-write branch of my database — schema and data — to develop and test against production-shaped datafullproof ↗
“Point-in-time recovery restores a database to a specific past moment, e.g. after an accidental drop”
Restore or branch the database to any point in time within the retention window to recover from bad writesfullproof ↗
“Documented 99.999999999% durability with sub-10ms latency SLA”
Add read replicas and rely on documented high-availability and failover behaviorpartialproof ↗
“Pro/Enterprise customers can bring their own S3 / S3-express buckets so data stays in their infrastructure”
Choose where my data is stored (region/residency)partialproof ↗
“Per-database encryption with customer-held keys and bring-your-own-cloud deployment for controlled data residency”
Choose where my data is stored (region/residency)partialproof ↗
“Dump a production database and use it locally for development”
Import an existing production database with minimal downtime using a documented migration pathpartialproof ↗
“CLI can create a new branch directly from an existing database”
Create an instant copy-on-write branch of my database — schema and data — to develop and test against production-shaped datafullproof ↗
Contradicted (2)
“Fully backwards-compatible with SQLite”
I get real engine compatibility — the Postgres, MySQL, or SQLite dialect and extensions my existing code expects — not a lookalike subsetdisputedproof ↗
“CLI can dump a database's contents to a SQL file for export”
Export all of my data in open formats and leavedisputedproof ↗
Undersold (18)
My coding agent can provision a database end to end — create it, fetch the connection string, apply schema, and run queries — through the API, CLI, or MCP without touching the dashboardfullproof ↗
Point an agent at llms.txt or agent-oriented docsfullproof ↗
Run the product headlessly / in CI for automationfullproof ↗
Drive the product through a documented public APIfullproof ↗
Issue scoped/least-privilege API credentials for an agentfullproof ↗
Set up automations that run autonomously in the backgroundpartialproof ↗
Operate the product with natural-language commandsfullproof ↗
Test against a sandbox environment without touching production datafullproof ↗
Perform bulk operations across many items at oncefullproof ↗
Reset a branch from its parent or restore it to an earlier state without rebuilding from a dumppartialproof ↗
Query over HTTP or WebSockets from serverless and edge functions with an official driver built for short-lived connectionspartialproof ↗
Do everything through the API that I can do in the UIpartialproof ↗
Read the product's source under an open licensepartialproof ↗
A genuinely usable free tier lets me run real prototypes before payingfullproof ↗
Automatic backups run on a schedule I can see and configure, and restores are self-servepartialproof ↗
Claims outside our story set (3)
Real capability claims found in Turso’s own materials, but no story in this arena’s taxonomy covers them yet — that’s feedback on the taxonomy, not a mark against the product.
“SDK exposes push() and pull() calls to sync a local embedded replica with the cloud database”
source ↗“Restrict network access to databases via AWS VPC allow lists”
source ↗“Multiple writers can write concurrently with zero conflicts and no locking”
source ↗
Pricing signals
- $0.75per GB-monthpay-as-you-goDeveloper plan storage overage rate (pay-as-you-go per GB beyond included quota)source ↗as of 2026-09-07
- $0.5per GB-monthpay-as-you-goScaler plan storage overage ratesource ↗as of 2026-09-07
- freeper GB-monthfree tierFree plan includes 5GB storage and 500 Million monthly rows read at no costsource ↗as of 2026-09-07
- $4.99per month (entry plan)entry planDeveloper plan sticker pricesource ↗as of 2026-09-07
Extracted verbatim from the vendor’s own pricing page — hover a figure for the exact quote.
Business model
Free plan (100 databases, 5GB), then flat monthly plans (Developer/Scaler/Pro) with metered overages on storage, rows read/written, and syncs; enterprise adds dedicated cloud and BYOC.
pricing ↗Score trend
How this product’s scores have moved as evidence and verdicts are re-derived — a point per change, not per day.
Try Experimental
Run it in the microterminal →Recorded agent sessions — and a live MCP handshake where the vendor ships one.
Flag
⚑ Flag a verdictThink a verdict is wrong? Opens a prefilled GitHub issue — or use the ⚑ next to any verdict above.
For agents
Agent surface uptime MCP 100% · llms.txt 100% (30d, checked every 6h since Sep 8 '26)