Rank #3 of 5 in Data Pipelines & ELT
 vs Airbyte
 vs Fivetran
 vs dlt
 vs Meltano
Showcase
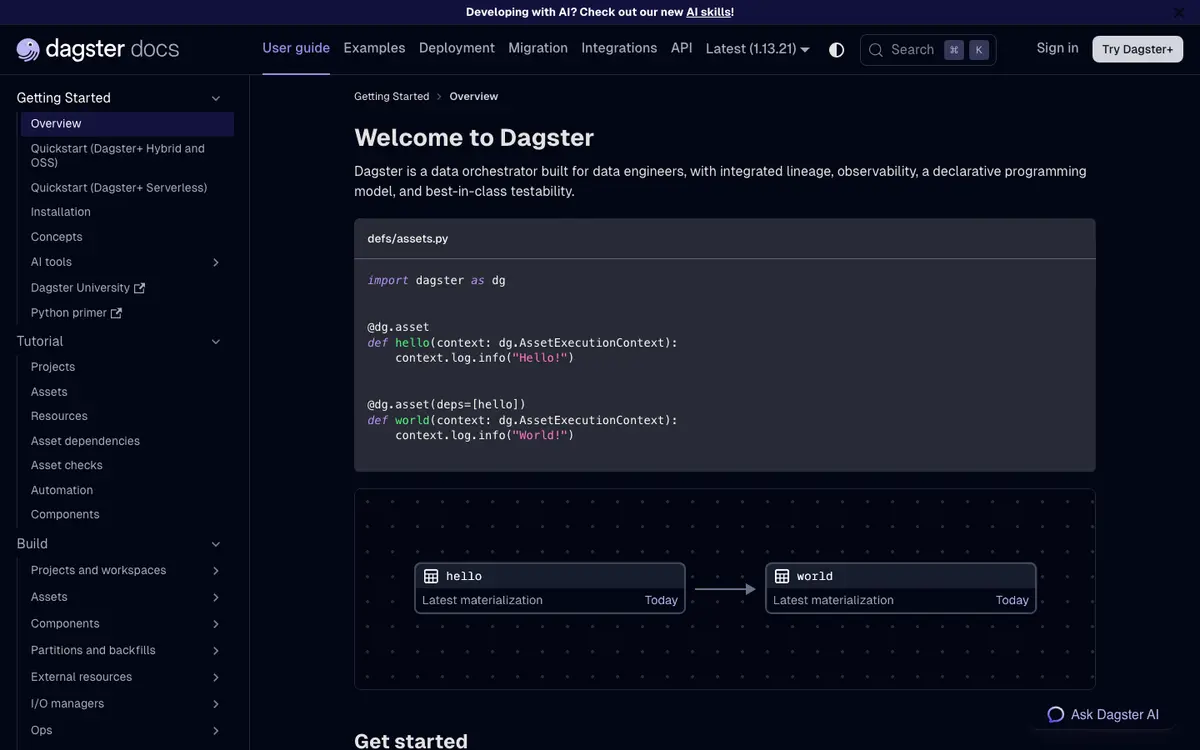
Try itExperimental
See what an agent can do with Dagster before you ever sign up. Pick a story: recorded sessions replay real probe-harness transcripts; sandboxed self-drive sessions are designed and gated (docs/TRY-IT.md).
$uvx dagster --versionrecorded session — replayed, not liveVerified integrations
Connections to other tracked products — hover a chip for the verbatim evidence quote behind it.
By theme — the product's score on each story themeBy theme
Agenticness — how well agents can access and operate the productAgenticnessevidence →
How well agents can access and operate the product
Ai pipelines — stories about ai pipelines in this arenaAi pipelinesevidence →
Stories about ai pipelines in this arena
Automation depth — how much of the product can run unattendedAutomation depthevidence →
How much of the product can run unattended
Code first portability — stories about code first portability in this arenaCode first portabilityevidence →
Stories about code first portability in this arena
Connectors catalog — stories about connectors catalog in this arenaConnectors catalogevidence →
Stories about connectors catalog in this arena
Observability reliability — stories about observability reliability in this arenaObservability reliabilityevidence →
Stories about observability reliability in this arena
Openness — open source, data portability, and self-hosting storiesOpennessevidence →
Open source, data portability, and self-hosting stories
Orchestration scheduling — stories about orchestration scheduling in this arenaOrchestration schedulingevidence →
Stories about orchestration scheduling in this arena
Pricing cost — stories about pricing cost in this arenaPricing costevidence →
Stories about pricing cost in this arena
Privacy posture — data-handling and privacy storiesPrivacy postureevidence →
Data-handling and privacy stories
Reverse etl activation — stories about reverse etl activation in this arenaReverse etl activationevidence →
Stories about reverse etl activation in this arena
Schema evolution — stories about schema evolution in this arenaSchema evolutionevidence →
Stories about schema evolution in this arena
Sync replication — stories about sync replication in this arenaSync replicationevidence →
Stories about sync replication in this arena
Transformations dbt — stories about transformations dbt in this arenaTransformations dbtevidence →
Stories about transformations dbt in this arena
Story verdicts — every judged story with its evidenceStory verdicts
Follow the green: where the map greys out is where Dagster stops today. ✓ full · ~ partial · ! disputed · — none · n/a not applicable.
Agenticness — how well agents can access and operate the productAgenticness
How well agents can access and operate the product
API surface
Drive the product through a documented public API
~6/10
unlocks → Webhooks · Scoped API keys · Machine-readable spec · Versioning policy · The catalog tells me each connector's maturity, support level, and maintainer before I depend on it
Subscribe to events via webhooks
—0/10
Build against official SDKs
✓8/10
Issue scoped/least-privilege API credentials for an agent
—–
Connect an agent via an official MCP server
✓7/10
Download a machine-readable API spec (OpenAPI or equivalent)
—0/10
Rely on versioned APIs with a documented deprecation policy
—0/10
Test against a sandbox environment without touching production data
~6/10
Explore an interactive API reference with runnable examples
—0/10
Docs for agents
Point an agent at llms.txt or agent-oriented docs
✓9/10
Agentic features
Delegate tasks to a built-in AI assistant inside the product
—0/10
Operate the product with natural-language commands
~6/10
Plug MCP servers into this product so it can use their tools
—0/10
Get AI-generated insights and suggestions from my data inside the product
—0/10
Set up automations that run autonomously in the background
✓8/10
Ai pipelines — stories about ai pipelines in this arenaAi pipelines
Stories about ai pipelines in this arena
Automation depth — how much of the product can run unattendedAutomation depth
How much of the product can run unattended
Code first portability — stories about code first portability in this arenaCode first portability
Stories about code first portability in this arena
Connectors catalog — stories about connectors catalog in this arenaConnectors catalog
Stories about connectors catalog in this arena
Observability reliability — stories about observability reliability in this arenaObservability reliability
Stories about observability reliability in this arena
Tell how fresh each destination table is and get warned when a pipeline misses its expected cadence
~6/10
I see run status, logs, and row counts per sync, and failures alert me in Slack, email, or a webhook
~4/10
Transient failures retry automatically and interrupted syncs resume from checkpoints instead of restarting
—–
Openness — open source, data portability, and self-hosting storiesOpenness
Open source, data portability, and self-hosting stories
Orchestration scheduling — stories about orchestration scheduling in this arenaOrchestration scheduling
Stories about orchestration scheduling in this arena
I run and test a pipeline locally against a lightweight destination before it touches production
✓7/10
I see end-to-end lineage of my datasets — which sources, steps, and transformations produced each table
~6/10
I define dependencies between pipeline steps and datasets, and the platform orchestrates runs in the right order
✓9/10
Pricing cost — stories about pricing cost in this arenaPricing cost
Stories about pricing cost in this arena
Privacy posture — data-handling and privacy storiesPrivacy posture
Data-handling and privacy stories
Reverse etl activation — stories about reverse etl activation in this arenaReverse etl activation
Stories about reverse etl activation in this arena
Schema evolution — stories about schema evolution in this arenaSchema evolution
Stories about schema evolution in this arena
Sync replication — stories about sync replication in this arenaSync replication
Stories about sync replication in this arena
Backfill history or resync a single table without rebuilding the whole pipeline
~6/10
I replicate databases with log-based CDC (binlog/WAL) so I capture updates and deletes without hammering the source
—0/10
Syncs move only new and changed records — cursor and state management handled for me, not full reloads
—0/10
I control sync frequency per pipeline — from sub-hour schedules to cron expressions and manual triggers
✓8/10
Transformations dbt — stories about transformations dbt in this arenaTransformations dbt
Stories about transformations dbt in this arena
Sorted by importance (agentic first) (high → low) · 53/53 stories · click a row’s chevron for the rationale and evidence
Connect an agent via an official MCP server G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 3 | full | 7/10 | Tprobed | |
Drive the product through a documented public API G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 3 | partial | 6/10 | Tprobed | |
Delegate tasks to a built-in AI assistant inside the product G Agentic features | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 3 | none | 0/10 | ||
Plug MCP servers into this product so it can use their tools G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 3 | none | 0/10 | ||
Point an agent at llms.txt or agent-oriented docs G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | full | 9/10 | Tprobed | |
Use an official CLI G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | full | 9/10 | Tprobed | |
Build against official SDKs G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | full | 8/10 | Tprobed | |
Run the product headlessly / in CI for automation G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | full | 8/10 | Tprobed | |
Set up automations that run autonomously in the background G Agentic features | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | full | 8/10 | Tprobed | |
Operate the product with natural-language commands G Agentic features | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | partial | 6/10 | Tprobed | |
Download a machine-readable API spec (OpenAPI or equivalent) G Api quality | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | none | 0/10 | ||
Explore an interactive API reference with runnable examples G Api quality | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | none | 0/10 | ||
Get AI-generated insights and suggestions from my data inside the product G Agentic features | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | none | 0/10 | ||
Rely on versioned APIs with a documented deprecation policy G Api quality | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | none | 0/10 | ||
Subscribe to events via webhooks G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | none | 0/10 | ||
Issue scoped/least-privilege API credentials for an agent G Agent access | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 2 | none | untested | none yet | |
Test against a sandbox environment without touching production data G Api quality | ai-native user | Agenticness — how well agents can access and operate the productAgenticness | 1 | partial | 6/10 | Tprobed | |
Self-host the core product G | ai-native user | Openness — open source, data portability, and self-hosting storiesOpenness | 3 | full | 9/10 | Tprobed | |
A coding agent can scaffold, configure, and run a complete pipeline headlessly through the CLI or API C Ai build | ai-native user | Ai pipelines — stories about ai pipelines in this arenaAi pipelines | 3 | full | 8/10 | Tprobed | |
Define rules that trigger actions automatically on events G | ai-native user | Automation depth — how much of the product can run unattendedAutomation depth | 3 | full | 8/10 | Tprobed | |
I pick from a broad catalog of maintained connectors for the SaaS APIs, databases, and files my company actually uses C Catalog | data engineer | Connectors catalog — stories about connectors catalog in this arenaConnectors catalog | 3 | partial | 6/10 | Xcommunity | |
Upstream schema changes are detected and propagated by a policy I choose, instead of silently breaking loads C Evolution | data engineer | Schema evolution — stories about schema evolution in this arenaSchema evolution | 3 | partial | 5/10 | Cclaimed | |
Export all of my data in open formats and leave G | ai-native user | Openness — open source, data portability, and self-hosting storiesOpenness | 3 | partial | 4/10 | Cclaimed | |
I see run status, logs, and row counts per sync, and failures alert me in Slack, email, or a webhook C Monitoring | data engineer | Observability reliability — stories about observability reliability in this arenaObservability reliability | 3 | partial | 4/10 | Cclaimed | |
AI drafts a working connector from API documentation — auth, pagination, streams — that I review and ship C Ai build | ai-native user | Ai pipelines — stories about ai pipelines in this arenaAi pipelines | 3 | none | 0/10 | ||
I replicate databases with log-based CDC (binlog/WAL) so I capture updates and deletes without hammering the source C Cdc | data engineer | Sync replication — stories about sync replication in this arenaSync replication | 3 | none | 0/10 | ||
Syncs move only new and changed records — cursor and state management handled for me, not full reloads C Incremental | data engineer | Sync replication — stories about sync replication in this arenaSync replication | 3 | none | 0/10 | ||
Prevent my data from being used to train AI models G | ai-native user | Privacy posture — data-handling and privacy storiesPrivacy posture | 3 | n/a | untested | none yet | |
I define dependencies between pipeline steps and datasets, and the platform orchestrates runs in the right order C Orchestration | data engineer | Orchestration scheduling — stories about orchestration scheduling in this arenaOrchestration scheduling | 2 | full | 9/10 | Tprobed | |
Dbt transformations run against freshly loaded data as part of the pipeline, not on a blind timer C Dbt | analytics engineer | Transformations dbt — stories about transformations dbt in this arenaTransformations dbt | 2 | full | 8/10 | Xcommunity | |
I control sync frequency per pipeline — from sub-hour schedules to cron expressions and manual triggers C Scheduling | data engineer | Sync replication — stories about sync replication in this arenaSync replication | 2 | full | 8/10 | Tprobed | |
My pipelines are plain code and config in my own repository — versioned, reviewed, and portable like any software C Code first | data engineer | Code first portability — stories about code first portability in this arenaCode first portability | 2 | full | 8/10 | Tprobed | |
Schedule recurring jobs or workflows G | ai-native user | Automation depth — how much of the product can run unattendedAutomation depth | 2 | full | 8/10 | Tprobed | |
I run and test a pipeline locally against a lightweight destination before it touches production C Dev loop | data engineer | Orchestration scheduling — stories about orchestration scheduling in this arenaOrchestration scheduling | 2 | full | 7/10 | Tprobed | |
An agent can check sync status, diagnose a failed run, and re-trigger it through an API or MCP server C Ai operate | ai-native user | Ai pipelines — stories about ai pipelines in this arenaAi pipelines | 2 | partial | 6/10 | Tprobed | |
Backfill history or resync a single table without rebuilding the whole pipeline C Backfill | data engineer | Sync replication — stories about sync replication in this arenaSync replication | 2 | partial | 6/10 | Cclaimed | |
I build a custom connector for a long-tail API with a supported framework or low-code builder, not a fork C Custom connectors | data engineer | Connectors catalog — stories about connectors catalog in this arenaConnectors catalog | 2 | partial | 6/10 | Cclaimed | |
I see end-to-end lineage of my datasets — which sources, steps, and transformations produced each table C Lineage | data engineer | Orchestration scheduling — stories about orchestration scheduling in this arenaOrchestration scheduling | 2 | partial | 6/10 | Cclaimed | |
Do everything through the API that I can do in the UI G | ai-native user | Openness — open source, data portability, and self-hosting storiesOpenness | 2 | partial | 5/10 | Tprobed | |
Perform bulk operations across many items at once G | ai-native user | Automation depth — how much of the product can run unattendedAutomation depth | 2 | partial | 5/10 | Tprobed | |
I load to the major warehouses and lakes — Snowflake, BigQuery, Databricks, Postgres, object storage — without changing pipelines C Destinations | data engineer | Code first portability — stories about code first portability in this arenaCode first portability | 2 | partial | 4/10 | Cclaimed | |
Control data retention and deletion G | ai-native user | Privacy posture — data-handling and privacy storiesPrivacy posture | 2 | partial | 3/10 | Cclaimed | |
The pricing model is published and predictable — I can estimate what a new source costs before connecting it G Pricing | data platform lead | Pricing cost — stories about pricing cost in this arenaPricing cost | 2 | none | 0/10 | ||
Choose where my data is stored (region/residency) G | ai-native user | Privacy posture — data-handling and privacy storiesPrivacy posture | 2 | n/a | untested | none yet | |
I sync modeled warehouse data back into SaaS tools (CRM, ads, support) to activate it where teams work C Reverse etl | analytics engineer | Reverse etl activation — stories about reverse etl activation in this arenaReverse etl activation | 2 | none | untested | none yet | |
Opt out of telemetry and usage tracking G | ai-native user | Privacy posture — data-handling and privacy storiesPrivacy posture | 2 | none | untested | none yet | |
Read the product's source under an open license G | ai-native user | Openness — open source, data portability, and self-hosting storiesOpenness | 2 | none | untested | none yet | |
Transient failures retry automatically and interrupted syncs resume from checkpoints instead of restarting C Recovery | data engineer | Observability reliability — stories about observability reliability in this arenaObservability reliability | 2 | none | untested | none yet | |
Tell how fresh each destination table is and get warned when a pipeline misses its expected cadence C Freshness | analytics engineer | Observability reliability — stories about observability reliability in this arenaObservability reliability | 1 | partial | 6/10 | Cclaimed | |
Loaded data lands as typed, deduplicated destination tables ready to query, not raw JSON blobs C Normalization | analytics engineer | Schema evolution — stories about schema evolution in this arenaSchema evolution | 1 | partial | 5/10 | Cclaimed | |
Version, review, and roll back my automations G | ai-native user | Automation depth — how much of the product can run unattendedAutomation depth | 1 | partial | 4/10 | Xcommunity | |
The catalog tells me each connector's maturity, support level, and maintainer before I depend on it C Catalog | data engineer | Connectors catalog — stories about connectors catalog in this arenaConnectors catalog | 1 | none | 0/10 | ||
Pipelines load into vector stores and LLM-ready formats so my agents can retrieve what was synced C Ai destinations | ai-native user | Ai pipelines — stories about ai pipelines in this arenaAi pipelines | 1 | none | untested | none yet |
Opportunities — the stories that would move this product's scores, from its own judged verdictsOpportunitiestop 8 of 36 stories with headroom
What would move Dagster’s scores — derived from its own judged verdicts, biggest headroom first. Each line quotes what the judge found missing; shipping it (or evidencing it publicly) is the fix.
Agenticness — how well agents can access and operate the productDelegate tasks to a built-in AI assistant inside the product
nonemoves Built-in AIimpact 45
Evidence shows Dagster ships an AI skill and an MCP server so that external coding agents (e.g., Claude, Copilot) can build/manage Dagster projects, but this is the inverse of the story — it makes Dagster controllable by agents, not a built-in assistant living inside Dagster's own UI/product that a user can delegate tasks to.
Agenticness — how well agents can access and operate the productPlug MCP servers into this product so it can use their tools
nonemoves agent-readyimpact 45
Evidence only shows Dagster exposing itself as an MCP server (Dagster+ MCP server, dagster-docs-14/probe-3) so external AI agents can call Dagster's tools — the opposite direction of the story, which asks whether a user can plug external MCP servers into Dagster so Dagster can use their tools.
Ai pipelines — stories about ai pipelines in this arenaAI drafts a working connector from API documentation — auth, pagination, streams — that I review and ship
nonemoves PA Scoreimpact 30
Dagster's evidence shows AI coding-agent skills, an MCP server, and CLI scaffolding for generic Dagster projects/components, plus integrations with connector tools (Airbyte, Fivetran, dlt), but there is no evidence of an AI feature that drafts a working connector (auth, pagination, streams) directly from API documentation for review and shipping.
Sync replication — stories about sync replication in this arenaI replicate databases with log-based CDC (binlog/WAL) so I capture updates and deletes without hammering the source
nonemoves PA Scoreimpact 30
Dagster's evidence shows it orchestrates and triggers syncs via Airbyte/Fivetran/dlt integrations, but nothing in the pack describes Dagster itself (or these integrations, as documented) performing log-based CDC (binlog/WAL) capture of inserts/updates/deletes.
Sync replication — stories about sync replication in this arenaSyncs move only new and changed records — cursor and state management handled for me, not full reloads
nonemoves PA Scoreimpact 30
Dagster orchestrates external sync tools (Fivetran, Airbyte, dlt) and represents their connectors as assets, but the evidence never shows Dagster itself managing cursors/incremental-state for syncs — that logic lives in the underlying EL tools, not in Dagster's own asset/partition framework.
Agenticness — how well agents can access and operate the productGet AI-generated insights and suggestions from my data inside the product
nonemoves Built-in AIimpact 30
Missing: any evidence of AI-generated insights/suggestions about data content, in-product analytics copilot, or anomaly detection surfaced to users.
Agenticness — how well agents can access and operate the productIssue scoped/least-privilege API credentials for an agent
nonemoves agent-readyimpact 30
Missing: any mention of API tokens, scoped credentials, RBAC for agent access, or least-privilege key issuance mechanisms.
Agenticness — how well agents can access and operate the productSubscribe to events via webhooks
nonemoves agent-readyimpact 30
Dagster documents sensors (event-driven triggers) and Dagster+ alerts, but no evidence describes an actual webhook subscription mechanism for external systems to receive event notifications from Dagster.
Showing the top 8 of 36 — every none/partial verdict in the story verdicts table is headroom.
Think a verdict is wrong? Every verdicts-table row has a Flag link — see the methodology.
Coverage map — which docs area, API section, or community source covers which judged storiesCoverage map11 surfaces · 33 covered stories
Where the cited evidence behind each covered verdict came from — the same citations the verdicts table shows, no extra judging.
Guides docs23 stories
- Run the product headlessly / in CI for automation
- Build against official SDKs
- Set up automations that run autonomously in the background
- Test against a sandbox environment without touching production data
- A coding agent can scaffold, configure, and run a complete pipeline headlessly through the CLI or API
- An agent can check sync status, diagnose a failed run, and re-trigger it through an API or MCP server
- Define rules that trigger actions automatically on events
- Schedule recurring jobs or workflows
- Version, review, and roll back my automations
- My pipelines are plain code and config in my own repository — versioned, reviewed, and portable like any software
- I load to the major warehouses and lakes — Snowflake, BigQuery, Databricks, Postgres, object storage — without changing pipelines
- I build a custom connector for a long-tail API with a supported framework or low-code builder, not a fork
- Tell how fresh each destination table is and get warned when a pipeline misses its expected cadence
- I see run status, logs, and row counts per sync, and failures alert me in Slack, email, or a webhook
- Export all of my data in open formats and leave
- I run and test a pipeline locally against a lightweight destination before it touches production
- I see end-to-end lineage of my datasets — which sources, steps, and transformations produced each table
- I define dependencies between pipeline steps and datasets, and the platform orchestrates runs in the right order
- Upstream schema changes are detected and propagated by a policy I choose, instead of silently breaking loads
- Loaded data lands as typed, deduplicated destination tables ready to query, not raw JSON blobs
- Backfill history or resync a single table without rebuilding the whole pipeline
- I control sync frequency per pipeline — from sub-hour schedules to cron expressions and manual triggers
- Dbt transformations run against freshly loaded data as part of the pipeline, not on a blind timer
Getting started docs21 stories
- Point an agent at llms.txt or agent-oriented docs
- Run the product headlessly / in CI for automation
- Connect an agent via an official MCP server
- Use an official CLI
- Drive the product through a documented public API
- Build against official SDKs
- Set up automations that run autonomously in the background
- Operate the product with natural-language commands
- Test against a sandbox environment without touching production data
- A coding agent can scaffold, configure, and run a complete pipeline headlessly through the CLI or API
- An agent can check sync status, diagnose a failed run, and re-trigger it through an API or MCP server
- Perform bulk operations across many items at once
- Define rules that trigger actions automatically on events
- Schedule recurring jobs or workflows
- My pipelines are plain code and config in my own repository — versioned, reviewed, and portable like any software
- Do everything through the API that I can do in the UI
- Export all of my data in open formats and leave
- Self-host the core product
- I run and test a pipeline locally against a lightweight destination before it touches production
- I define dependencies between pipeline steps and datasets, and the platform orchestrates runs in the right order
- I control sync frequency per pipeline — from sub-hour schedules to cron expressions and manual triggers
API reference8 stories
- Run the product headlessly / in CI for automation
- Use an official CLI
- Drive the product through a documented public API
- Build against official SDKs
- A coding agent can scaffold, configure, and run a complete pipeline headlessly through the CLI or API
- My pipelines are plain code and config in my own repository — versioned, reviewed, and portable like any software
- Do everything through the API that I can do in the UI
- Self-host the core product
Integrations docs8 stories
- Perform bulk operations across many items at once
- I load to the major warehouses and lakes — Snowflake, BigQuery, Databricks, Postgres, object storage — without changing pipelines
- I pick from a broad catalog of maintained connectors for the SaaS APIs, databases, and files my company actually uses
- I build a custom connector for a long-tail API with a supported framework or low-code builder, not a fork
- Do everything through the API that I can do in the UI
- I see end-to-end lineage of my datasets — which sources, steps, and transformations produced each table
- Loaded data lands as typed, deduplicated destination tables ready to query, not raw JSON blobs
- Dbt transformations run against freshly loaded data as part of the pipeline, not on a blind timer
Hacker News6 stories
- Test against a sandbox environment without touching production data
- Version, review, and roll back my automations
- I pick from a broad catalog of maintained connectors for the SaaS APIs, databases, and files my company actually uses
- I run and test a pipeline locally against a lightweight destination before it touches production
- I define dependencies between pipeline steps and datasets, and the platform orchestrates runs in the right order
- Dbt transformations run against freshly loaded data as part of the pipeline, not on a blind timer
About docs6 stories
- Perform bulk operations across many items at once
- Define rules that trigger actions automatically on events
- Version, review, and roll back my automations
- Tell how fresh each destination table is and get warned when a pipeline misses its expected cadence
- Control data retention and deletion
- Backfill history or resync a single table without rebuilding the whole pipeline
Deployment docs6 stories
- Run the product headlessly / in CI for automation
- Set up automations that run autonomously in the background
- My pipelines are plain code and config in my own repository — versioned, reviewed, and portable like any software
- I see run status, logs, and row counts per sync, and failures alert me in Slack, email, or a webhook
- Export all of my data in open formats and leave
- Self-host the core product
docs.dagster.io5 stories
- Build against official SDKs
- My pipelines are plain code and config in my own repository — versioned, reviewed, and portable like any software
- I build a custom connector for a long-tail API with a supported framework or low-code builder, not a fork
- I see end-to-end lineage of my datasets — which sources, steps, and transformations produced each table
- I define dependencies between pipeline steps and datasets, and the platform orchestrates runs in the right order
OpenAPI spec3 stories
Probe proofs — replayable recordings from the probe harnessProbe proofs
Replayable recordings from our probe harness — see the Prove-It protocol to submit one.
$uvx dagster --versionreproduced$ uvx dagster --version dagster, version 1.13.21
$mktemp -d && uvx create-dagster@latest project pa-probe --uv-sync && cd pa-probe && uv run dagster dev -p 13334 & curl http://127.0.0.1:13334/server_info # scaffold + real webserver boot, keylessreproduced$ mktemp -d && uvx create-dagster@latest project pa-probe --uv-sync && cd pa-probe && uv run dagster dev -p 13334 & curl http://127.0.0.1:13334/server_info # scaffold + real webserver boot, [redacted]less
uv.lock and virtual environment created.
Run `source pa-probe/.venv/bin/activate` to activate your project's virtual environment.
README.md pyproject.toml src tests uv.lock
2026-09-08 13:41:11 -0700 - dagster-webserver - INFO - Serving dagster-webserver on http://127.0.0.1:13334 in process 710
{"dagster_webserver_version":"1.13.21","dagster_version":"1.13.21","dagster_graphql_version":"1.13.21"}
Claims vs evidence — vendor claims reconciled against independent verdictsClaims vs evidence
12 of 16 testable claims verified · 1 contradicted → integrity 63/100
19 distinct capability claims found in Dagster’s own claimed-docs/GitHub materials, reconciled against our judge’s independent verdicts.
12
Verified
3
Unverified
1
Contradicted
18
Undersold
Verified (16)
“Assets can be defined in code describing how to produce and update them”
I define dependencies between pipeline steps and datasets, and the platform orchestrates runs in the right orderfullproof ↗
“Scaffold a new Dagster project using the official create-dagster CLI”
“Scaffold a new Dagster project using the official create-dagster CLI”
A coding agent can scaffold, configure, and run a complete pipeline headlessly through the CLI or APIfullproof ↗
“Schedules let you run jobs automatically at set intervals”
“Sensors trigger actions in response to internal or external events”
Define rules that trigger actions automatically on eventsfullproof ↗
“Declarative Automation launches asset executions based on asset status and dependency information”
Set up automations that run autonomously in the backgroundfullproof ↗
“Run subsets of dbt models, seeds, and snapshots via UI or API as part of the pipeline”
Dbt transformations run against freshly loaded data as part of the pipeline, not on a blind timerfullproof ↗
“FivetranAccountComponent represents Fivetran connectors as Dagster assets”
I pick from a broad catalog of maintained connectors for the SaaS APIs, databases, and files my company actually usespartialproof ↗
“DltLoadCollectionComponent represents a collection of dlt sources/pipelines as Dagster assets”
I pick from a broad catalog of maintained connectors for the SaaS APIs, databases, and files my company actually usespartialproof ↗
“Dagster can be deployed via Docker with dedicated containers for webserver, daemon, and code locations, enabling self-hosting”
“Dagster maintains an AI skill giving coding agents context and patterns for building Dagster projects”
Point an agent at llms.txt or agent-oriented docsfullproof ↗
“Dagster+ provides an official MCP server for accessing and acting on deployments within an AI session”
“Scaffold Dagster Component definitions from the command line via dg scaffold defs”
“Scaffold Dagster Component definitions from the command line via dg scaffold defs”
A coding agent can scaffold, configure, and run a complete pipeline headlessly through the CLI or APIfullproof ↗
“Encapsulate an entire ETL process as a single code-defined Dagster asset”
My pipelines are plain code and config in my own repository — versioned, reviewed, and portable like any softwarefullproof ↗
“Automation condition evaluations explain history-dependent logic by showing the remembered values behind decisions”
Define rules that trigger actions automatically on eventsfullproof ↗
Unverified (3)
“Asset checks can validate null values, schema conformance, and data freshness”
Tell how fresh each destination table is and get warned when a pipeline misses its expected cadencepartialproof ↗
“Dagster+ alerts notify you of critical deployment events for early issue detection”
I see run status, logs, and row counts per sync, and failures alert me in Slack, email, or a webhookpartialproof ↗
“Wiping/deleting dynamic partitions now supports multi-partitioned assets in a single action”
Backfill history or resync a single table without rebuilding the whole pipelinepartialproof ↗
Contradicted (1)
“Published tiered pricing plans (e.g. Solo Plan) with free trial for predictable cost estimation”
The pricing model is published and predictable — I can estimate what a new source costs before connecting itnoneproof ↗
Undersold (18)
Run the product headlessly / in CI for automationfullproof ↗
Drive the product through a documented public APIpartialproof ↗
Operate the product with natural-language commandspartialproof ↗
Test against a sandbox environment without touching production datapartialproof ↗
An agent can check sync status, diagnose a failed run, and re-trigger it through an API or MCP serverpartialproof ↗
Perform bulk operations across many items at oncepartialproof ↗
I load to the major warehouses and lakes — Snowflake, BigQuery, Databricks, Postgres, object storage — without changing pipelinespartialproof ↗
I build a custom connector for a long-tail API with a supported framework or low-code builder, not a forkpartialproof ↗
Do everything through the API that I can do in the UIpartialproof ↗
Export all of my data in open formats and leavepartialproof ↗
I run and test a pipeline locally against a lightweight destination before it touches productionfullproof ↗
I see end-to-end lineage of my datasets — which sources, steps, and transformations produced each tablepartialproof ↗
Upstream schema changes are detected and propagated by a policy I choose, instead of silently breaking loadspartialproof ↗
Loaded data lands as typed, deduplicated destination tables ready to query, not raw JSON blobspartialproof ↗
I control sync frequency per pipeline — from sub-hour schedules to cron expressions and manual triggersfullproof ↗
Claims outside our story set (1)
Real capability claims found in Dagster’s own materials, but no story in this arena’s taxonomy covers them yet — that’s feedback on the taxonomy, not a mark against the product.
“Airbyte integration lets you trigger and orchestrate Airbyte syncs from Dagster”
source ↗
Business model
Apache-2.0 open-source core is free to self-host; Dagster+ has a free Solo tier, a Starter tier with usage-based credits, and custom Pro pricing (Serverless or Hybrid).
pricing ↗Score trend
How this product’s scores have moved as evidence and verdicts are re-derived — a point per change, not per day.
Try Experimental
Run it in the microterminal →Recorded agent sessions — and a live MCP handshake where the vendor ships one.
Flag
⚑ Flag a verdictThink a verdict is wrong? Opens a prefilled GitHub issue — or use the ⚑ next to any verdict above.
For agents
Agent surface uptime llms.txt up (tracking since Sep 10 '26)